Model Gallery

127 models from 1 repositories

Filter by type:

Filter by tags:

qwen3.8-27b-defiance-iq4
Defiance combines HauhauCS's uncensored Qwen3.8-27B weights with a customized Turbo Brilliance chat template for reasoning and roleplay. This IQ4_XS GGUF build uses llama.cpp and the embedded template, with a 32,768-token context. Text input only; MTP is not enabled.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-defiance-q6
Defiance combines HauhauCS's uncensored Qwen3.8-27B weights with a customized Turbo Brilliance chat template for reasoning and roleplay. This Q6_K_P GGUF build uses llama.cpp and the embedded template, with a 32,768-token context. Text input only; MTP is not enabled.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-imatrix-nvfp4-mtp
Qwen3.8-27B in cdiamond's iMatrix-calibrated mixed-precision NVFP4 build. Selected attention and feed-forward tensors retain higher precision. Includes the F16 vision projector and enables the embedded MTP draft head with one draft token per step.

Repository: localaiLicense: apache-2.0

huihui-qwen3.8-flash-next-abliterated-v2-q4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the abliteration without modifying the experts. This vision-language mixture-of-experts model uses the publisher's UD-Q4_K_XL GGUF and BF16 projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

huihui-qwen3.8-flash-next-abliterated-v2-iq4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the abliteration without modifying the experts. This vision-language mixture-of-experts model uses the publisher's UD-IQ4_XS GGUF and BF16 projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

swift-qwen3.8-27b
Swift-Qwen3.8-27B is UkisAI's reasoning-efficient fine-tune of Qwen3.8-27B. The publisher reports 58.3% fewer thinking tokens with less than 1% quality loss. This Q4_K_M GGUF includes the F16 vision projector and enables MTP speculative decoding. The weights use the Swift Open License v1.0.

Repository: localaiLicense: swift-open-license-1.0
qwen3.8-flash-next-uncensored
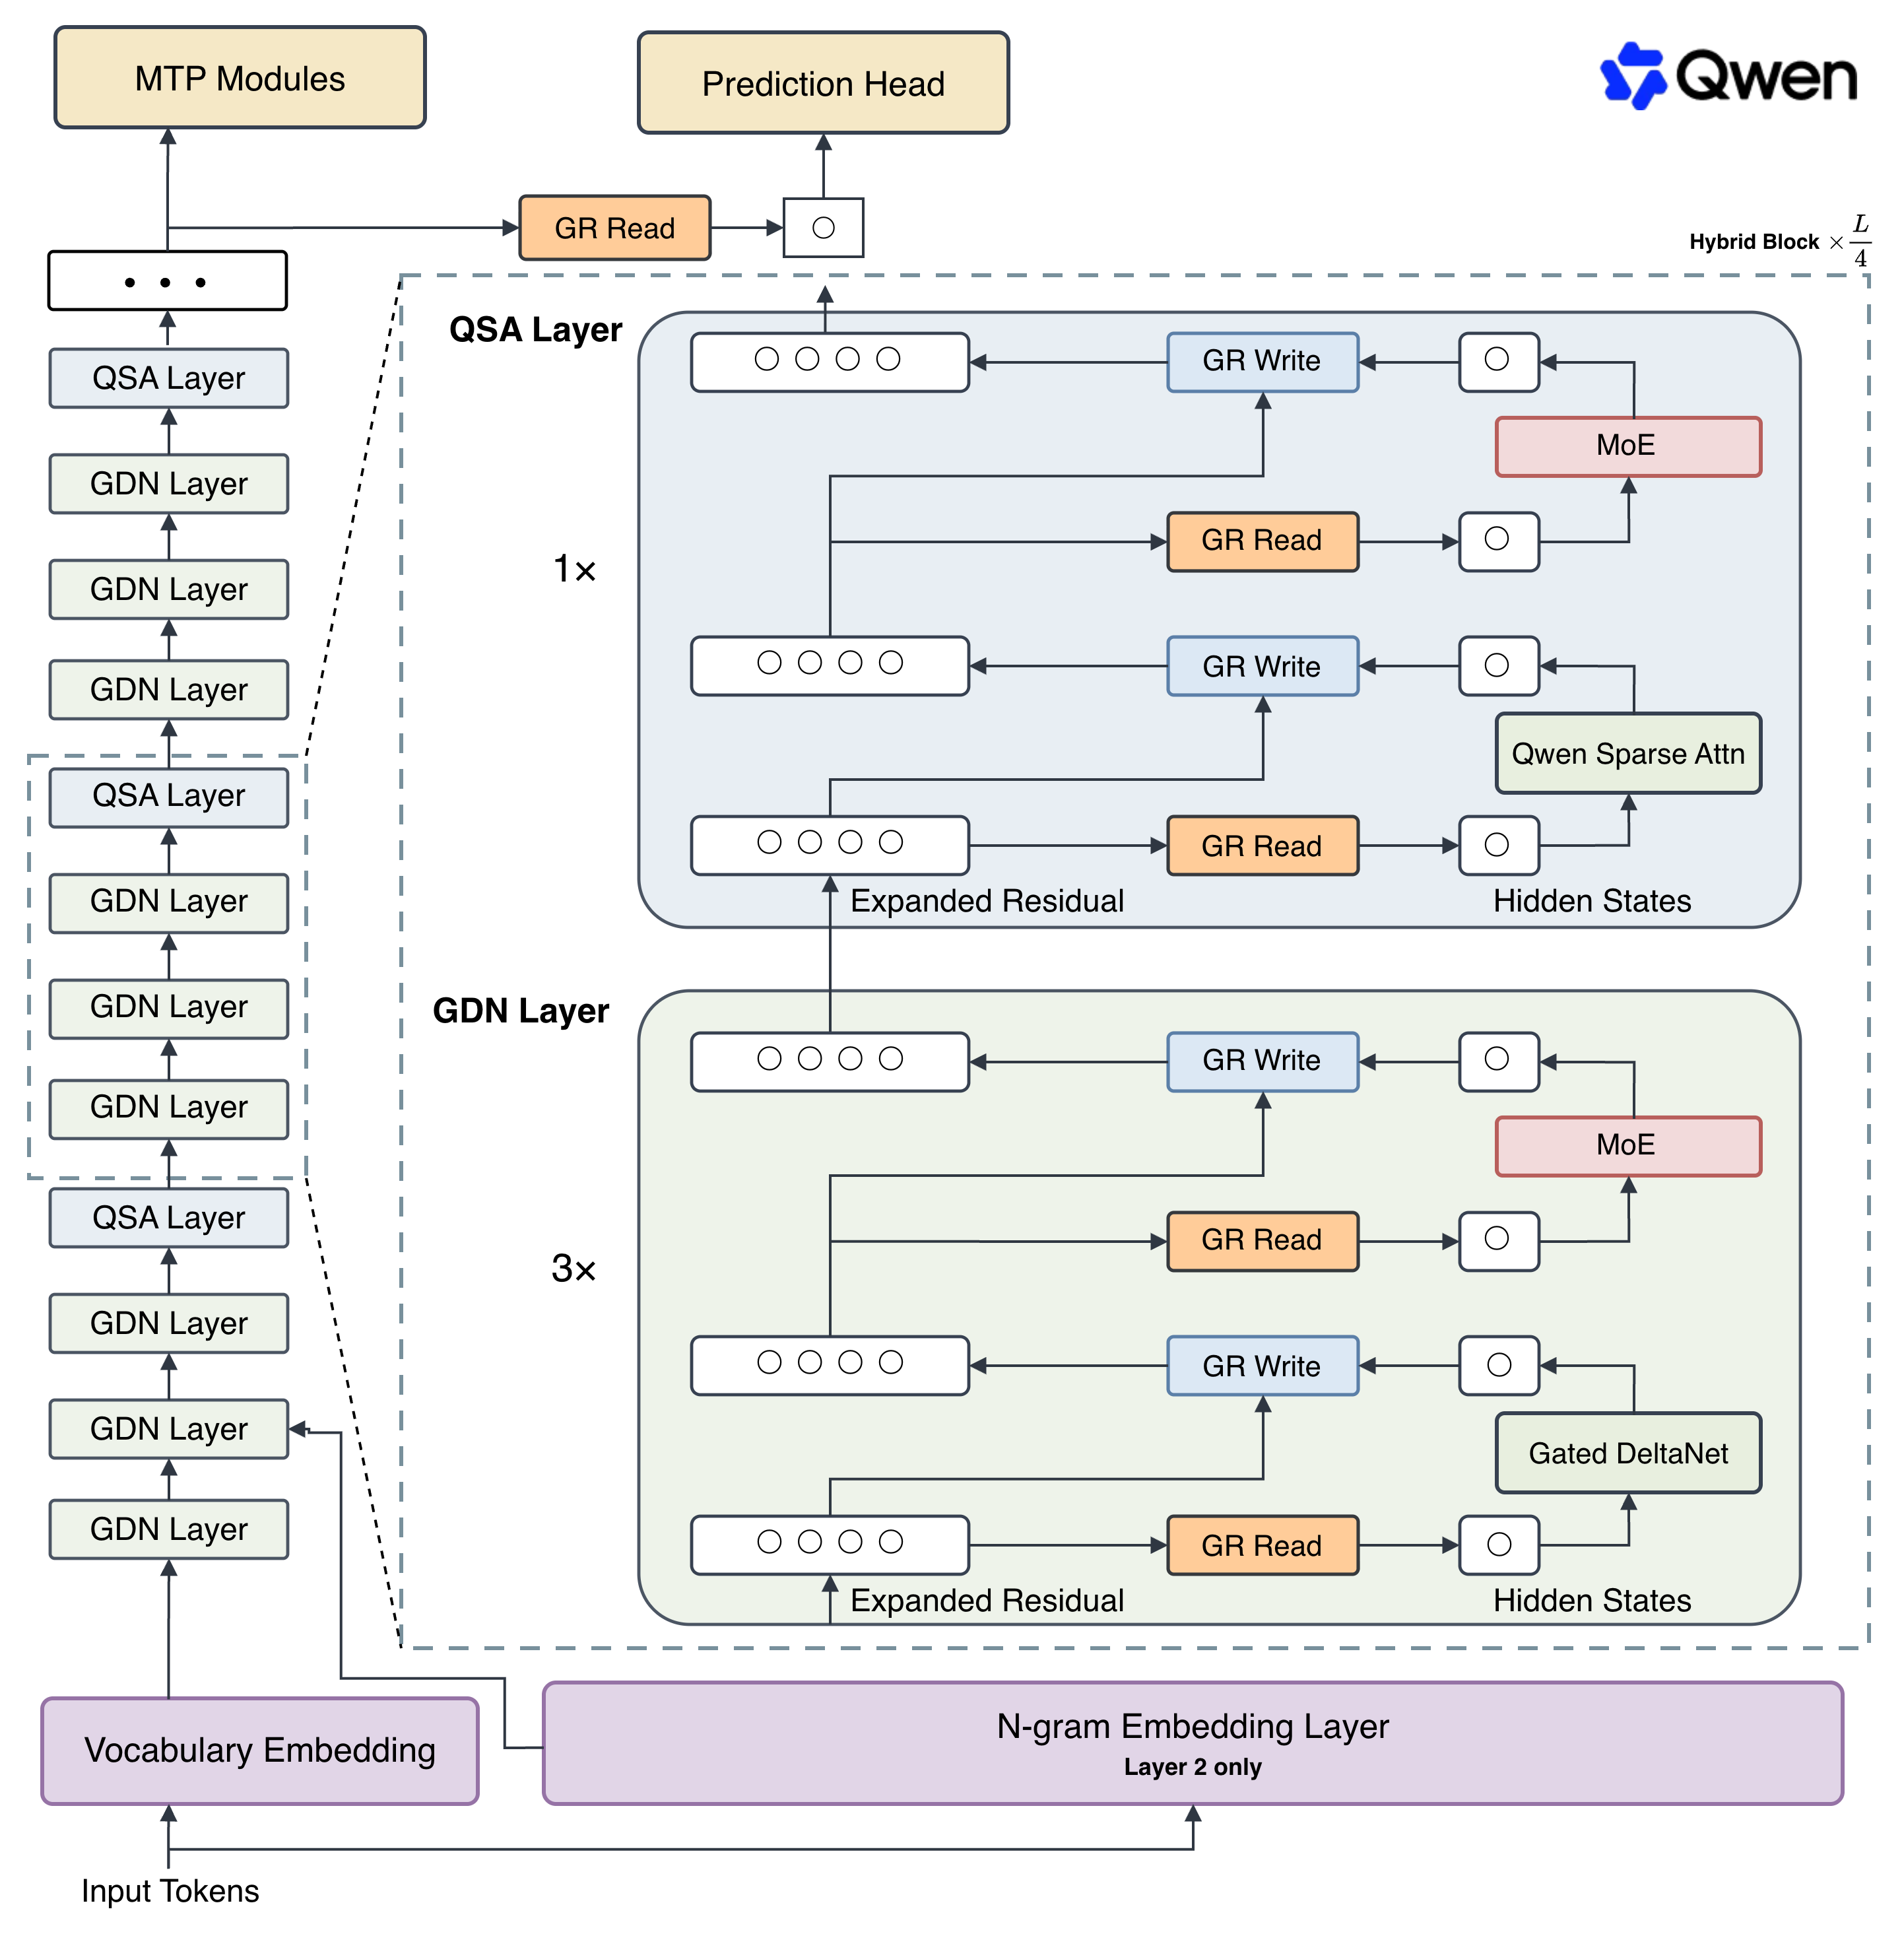
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0
qwen3.8-27b-fable-5-coding-distilled
A 27B Qwen3.8 fine-tune for coding, debugging, and agentic reasoning. This Q4_K_M GGUF build uses llama.cpp, the embedded chat template, and the F16 vision projector.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-fable-5-coding-distilled-q8
A 27B Qwen3.8 fine-tune for coding, debugging, and agentic reasoning. This Q8_0 GGUF build uses llama.cpp, the embedded chat template, and the F16 vision projector.

Repository: localaiLicense: apache-2.0

thinkingcap-qwen3.8-27b
ThinkingCap is a 27B Qwen3.8 fine-tune trained to reduce reasoning tokens, with text and image input. This Q4_K_M GGUF build uses llama.cpp, the embedded chat template, and the F16 vision projector. Licensed under PolyForm Small Business 1.0.0 with the publisher's personal-use grant; see the model license for permitted use.

Repository: localaiLicense: polyform-small-business-1.0.0

thinkingcap-qwen3.8-27b-q8
ThinkingCap is a 27B Qwen3.8 fine-tune trained to reduce reasoning tokens, with text and image input. This Q8_0 GGUF build uses llama.cpp, the embedded chat template, and the F16 vision projector. Licensed under PolyForm Small Business 1.0.0 with the publisher's personal-use grant; see the model license for permitted use.

Repository: localaiLicense: polyform-small-business-1.0.0

qwen3.8-27b-jumbo-fusion-q4
DavidAU's Jumbo Fusion edition of Qwen3.8-27B merges community fine-tunes and includes a custom template with reasoning and instruction modes. This Q4_K_M GGUF build supports text chat with a 32,768-token default context.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-jumbo-fusion-q8
DavidAU's Jumbo Fusion edition of Qwen3.8-27B merges community fine-tunes and includes a custom template with reasoning and instruction modes. This Q8_0 GGUF build supports text chat with a 32,768-token default context.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-turbo-brilliance-50x-q4
DavidAU's Turbo Brilliance 50X edition of Qwen3.8-27B includes a custom chat template with selectable reasoning and instruction modes. This Q4_K_M GGUF build includes the F16 vision projector for image input. Uses the embedded template with a 32,768-token context by default.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-turbo-brilliance-50x-q8
DavidAU's Turbo Brilliance 50X edition of Qwen3.8-27B includes a custom chat template with selectable reasoning and instruction modes. This Q8_0 GGUF build includes the F16 vision projector for image input. Uses the embedded template with a 32,768-token context by default.

Repository: localaiLicense: apache-2.0

qwen3.8-27b
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-uncensored-hauhaucs-aggressive-mtp
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-uncensored
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-turbo-fable-cold-fusion-735-882-heretic-uncensored-neo-coder-max-mtp
RELEASE #1 GGUFS [including detailed notes, how to use, benches and much more]: https://huggingface.co/DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU (release #1, others pending...) ( repo has 10+ other versions (and 3 branches) noted below that EXCEED the performance of all QWEN 27B models, including fine tunes. ) First, special thanks to Nightmedia for working on the first three stages prior to heretic'ing/post staging and benching everything (3 sections below). A number of my finetunes - both released and non-released - were used here as well as some third parties. Full details will be disclosed upon final release as the project shores up. THREE example generations [snippets] from STAGE1-PART2, STAGE1b-PART2 and STAGE2-rplus2 at the bottom of the page. Release(s) will be GGUFS first (linked here directly) then source code shortly thereafter [now released/open]. Some additional work and/ spawning of new branches from branch(es) below is still going on. NEW: Branch 3 added, see below. COMPLETED AND PENDING RELEASES: ...

Repository: localaiLicense: apache-2.0

huihui-qwen3.8-flash-next-abliterated-q4
Huihui's abliterated Qwen3.8-Flash-Next is a vision-language mixture-of-experts model modified to reduce refusals. This entry uses the publisher's UD-Q4_K_XL GGUF and BF16 vision projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

qwen3.8-flash-next-q4
Qwen3.8-Flash-Next is Qwen's 125B-parameter, 6B-active experimental vision-language mixture-of-experts model. It targets agentic coding, reasoning, tool use, and long-context workloads with a native 262K-token context window. This default entry uses Unsloth's UD-Q4_K_XL GGUF and BF16 vision projector. Linked variants offer Q8_0 and AtomicChat's smaller IQ4_XS and Q4_K_M builds with a separate n-gram table shard.

Repository: localaiLicense: other

Page 1