Filter by type:
Filter by tags:

qwen3.8-27b-imatrix-nvfp4-mtp
Qwen3.8-27B in cdiamond's iMatrix-calibrated mixed-precision NVFP4
build. Selected attention and feed-forward tensors retain higher
precision. Includes the F16 vision projector and enables the embedded
MTP draft head with one draft token per step.
Repository: localaiLicense: apache-2.0
qwen3.8-27b-nvfp4-mtp
Qwen3.8-27B in a compact NVFP4 GGUF format with its MTP draft head
embedded in the model file. This entry uses the medium tier, which keeps
the NVFP4 backbone while using higher-precision output and embedding
tensors. MTP speculative decoding proposes multiple tokens for the target
model to verify.
Repository: localaiLicense: apache-2.0

nemotron-3.5-lightning-30b-a3b-nvfp4
NVIDIA Nemotron 3.5 Lightning 30B-A3B in the official NVFP4 GGUF format.
This is the smallest linked build and retains the model's reasoning, coding,
tool-use, multilingual, and long-context capabilities.
Repository: localaiLicense: openmdw-1.1
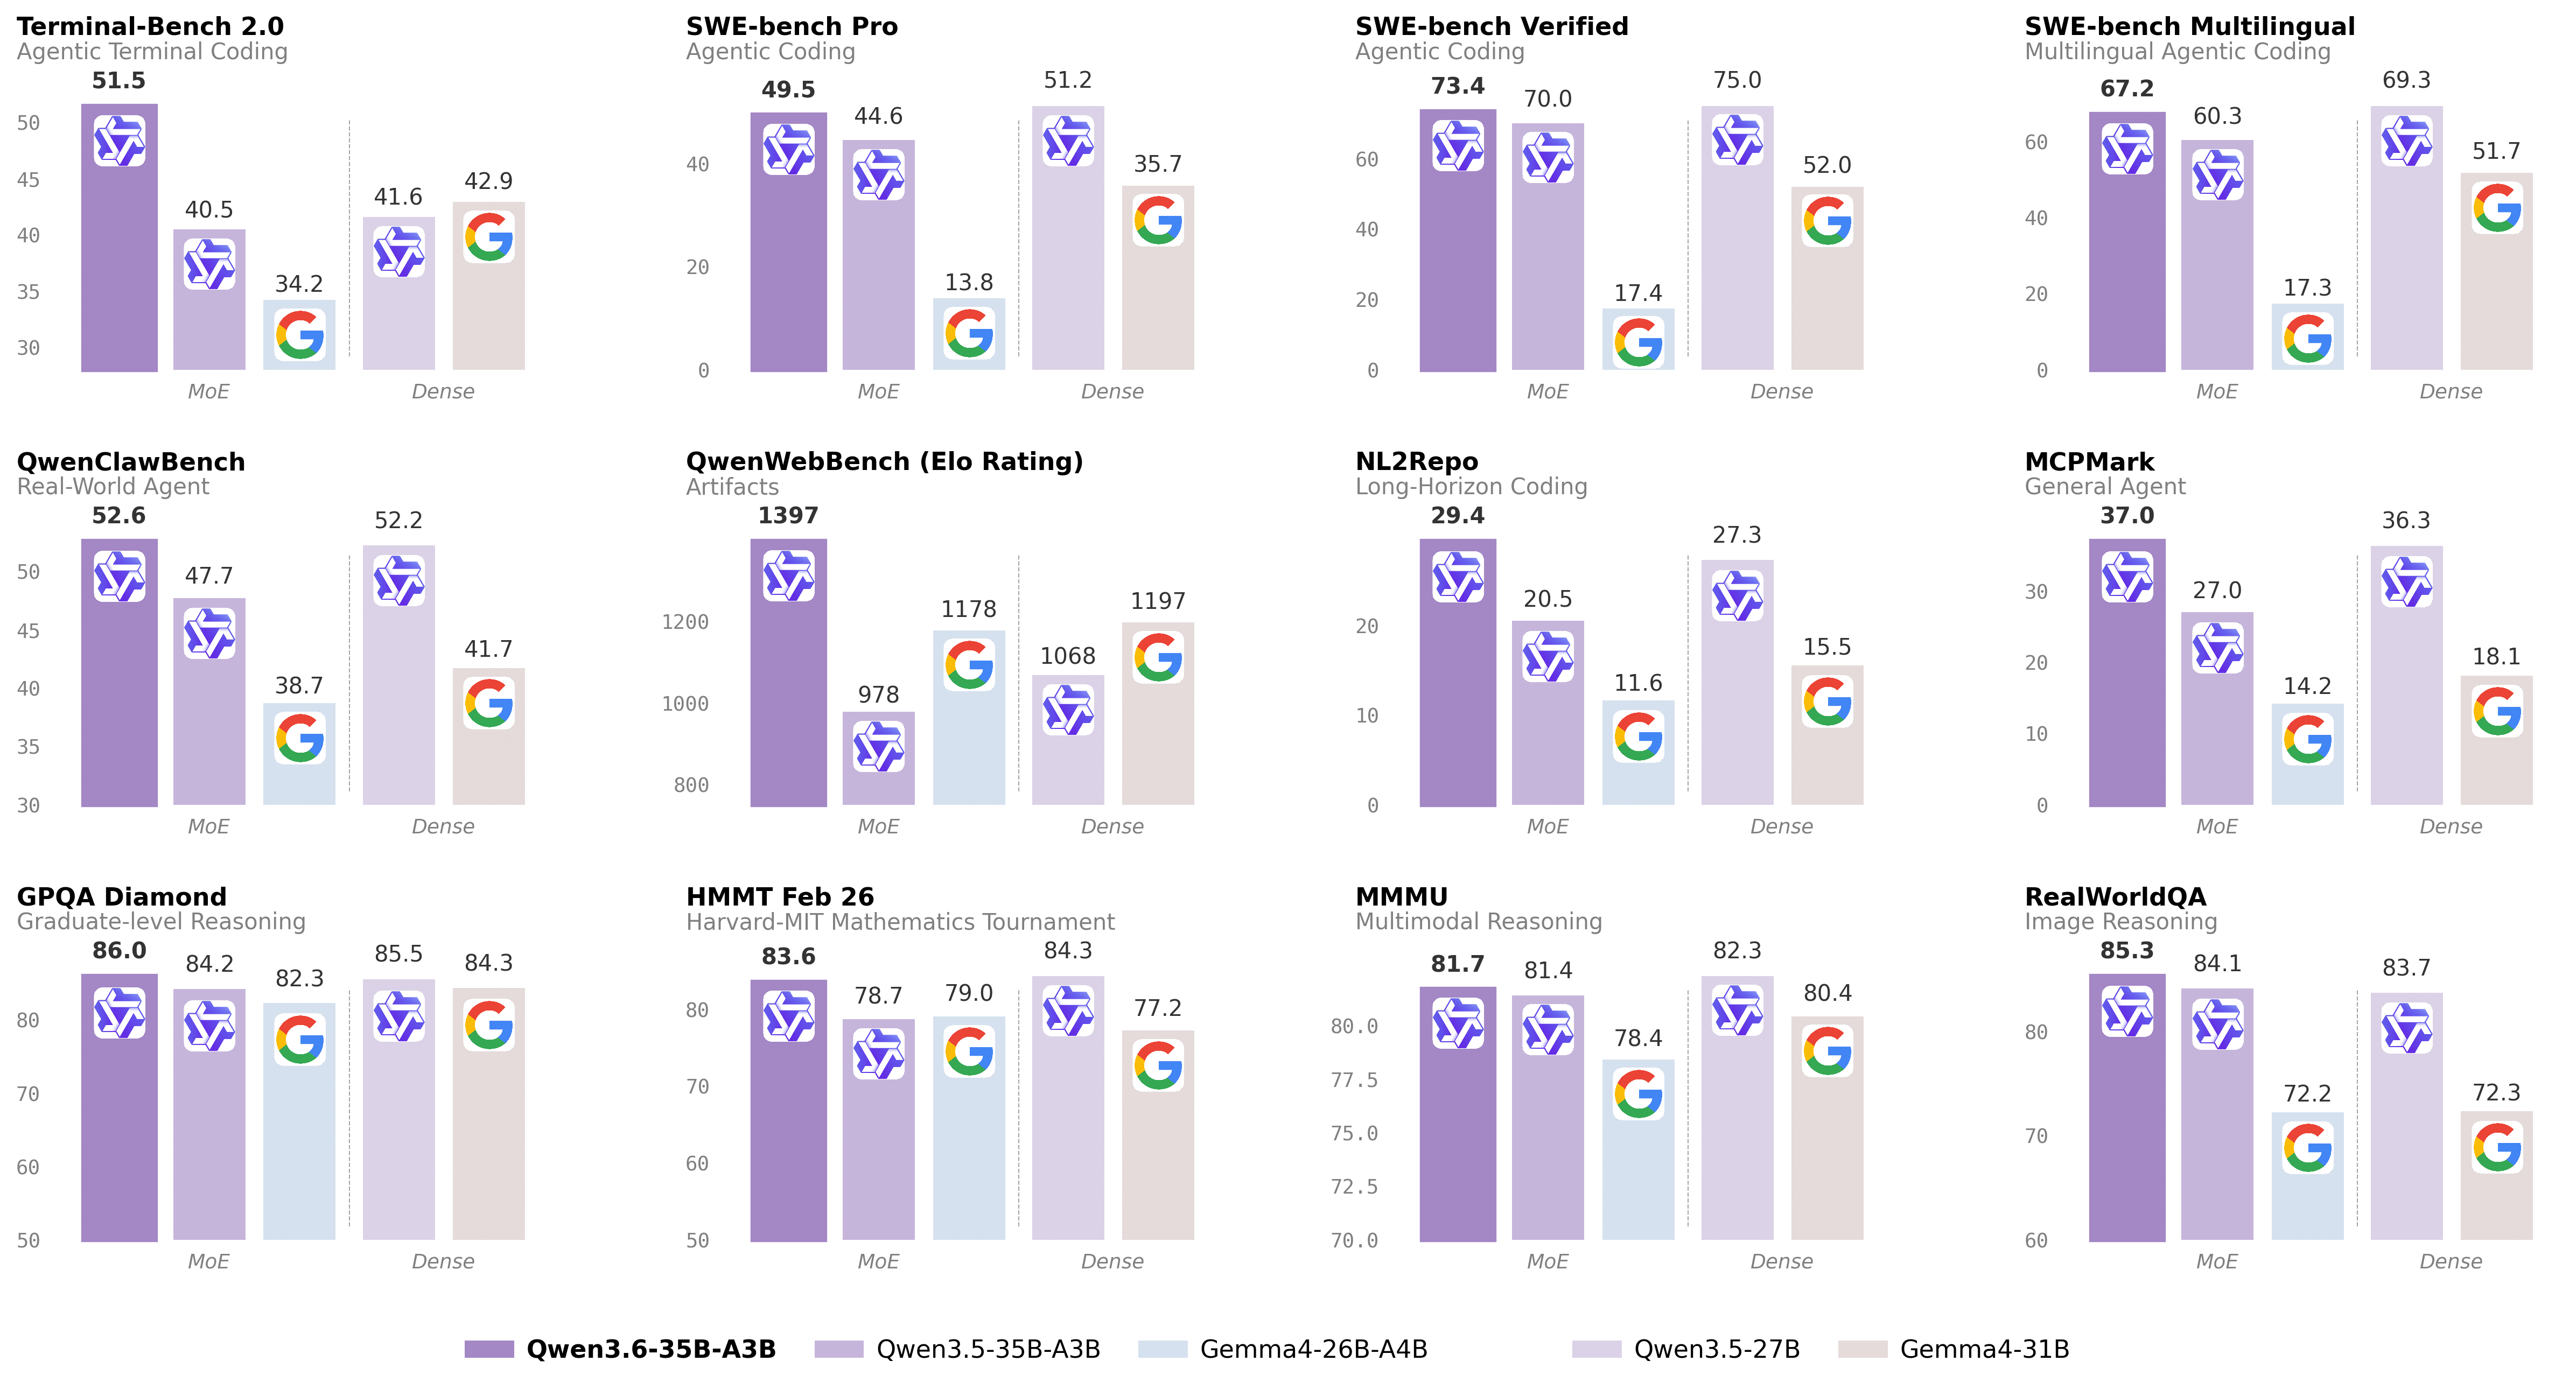
qwen3.6-35b-a3b-nvfp4-mtp
# Qwen3.6-35B-A3B
[](https://chat.qwen.ai)
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
## Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- **Agentic Coding:** the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- **Thinking Preservation:** we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post Qwen3.6-35B-A3B.
## Model Overview
...
Repository: localai
qwopus3.6-27b-v2-mtp-nvfp4
🪐 Qwopus3.6-27B-v2-MTP
MTP Release
Multi-Token Prediction reasoning model fine-tuned from Qwen3.6-27B
🧬 Trace Inversion & Negentropy
🧠 27B Parameters
⚡ Speculative Decoding
🛠️ Coding / DevOps / Math
💡 What is Qwopus3.6-27B-v2-MTP?
🪐 Qwopus3.6-27B-v2-MTP is a speed-oriented reasoning release built on top of Qwen3.6-27B. It keeps the Qwopus line's focus on reconstructed reasoning traces, coding discipline, DevOps procedures, and mathematical derivations, while adding Multi-Token Prediction for faster generation. The goal is simple: preserve the depth and structure of a 27B reasoning model while making real interactive use noticeably faster.
⚡ MTP DecodingAuxiliary future-token prediction improves throughput on long reasoning, code, math, and strict-format prompts.
🧩 Structured ReasoningInherits the Qwopus training recipe built around reconstructed step-by-step reasoning trajectories.
🧪 GB10 TestedValidated on a 30-question local benchmark across Logic, Coding, DevOps, Math, and Edge tasks.
🚀 Practical SpeedDesigned for workflows where strong answers matter, but waiting several extra minutes per task does not.
...
Repository: localai

qwopus3.6-27b-coder-mtp-nvfp4
🪐 Qwopus-3.6-27B-Coder
Coder SFT Release
Agentic Coding & Tool-Use Reasoning Model Fine-Tuned on Qwopus3.6-27B-v2
🧬 Trace Inversion & Negentropy
🧠 27B Dense Model
⚡ Agentic Coding
🛠️ Tool Calling & Agent
🏆 SWE-bench Verified: 67.0% (off-thinking)
💡 What is Qwopus-3.6-27B-Coder?
🪐 Qwopus-3.6-27B-Coder is a reasoning-enhanced agentic coding model built on top of Qwopus3.6-27B-v2. It inherits the powerful reasoning foundation of the v2 base — which achieved 87.43% MMLU-Pro (300ex) and 75.25% SWE-bench Verified — and further specializes it for agentic code generation, structured tool calling, debugging, and instruction-following in developer workflows. The model is designed to excel at repository-level coding tasks, multi-turn tool orchestration, and complex logical reasoning under realistic agent environments.
🧩 Agentic Coding
Optimized for repository-level coding, debugging, patch generation, and structured multi-step development workflows.
🛠️ Tool Calling
Learns from real agent trajectories with tool definitions, tool calls, and environment feedback for robust multi-turn execution.
...
Repository: localai
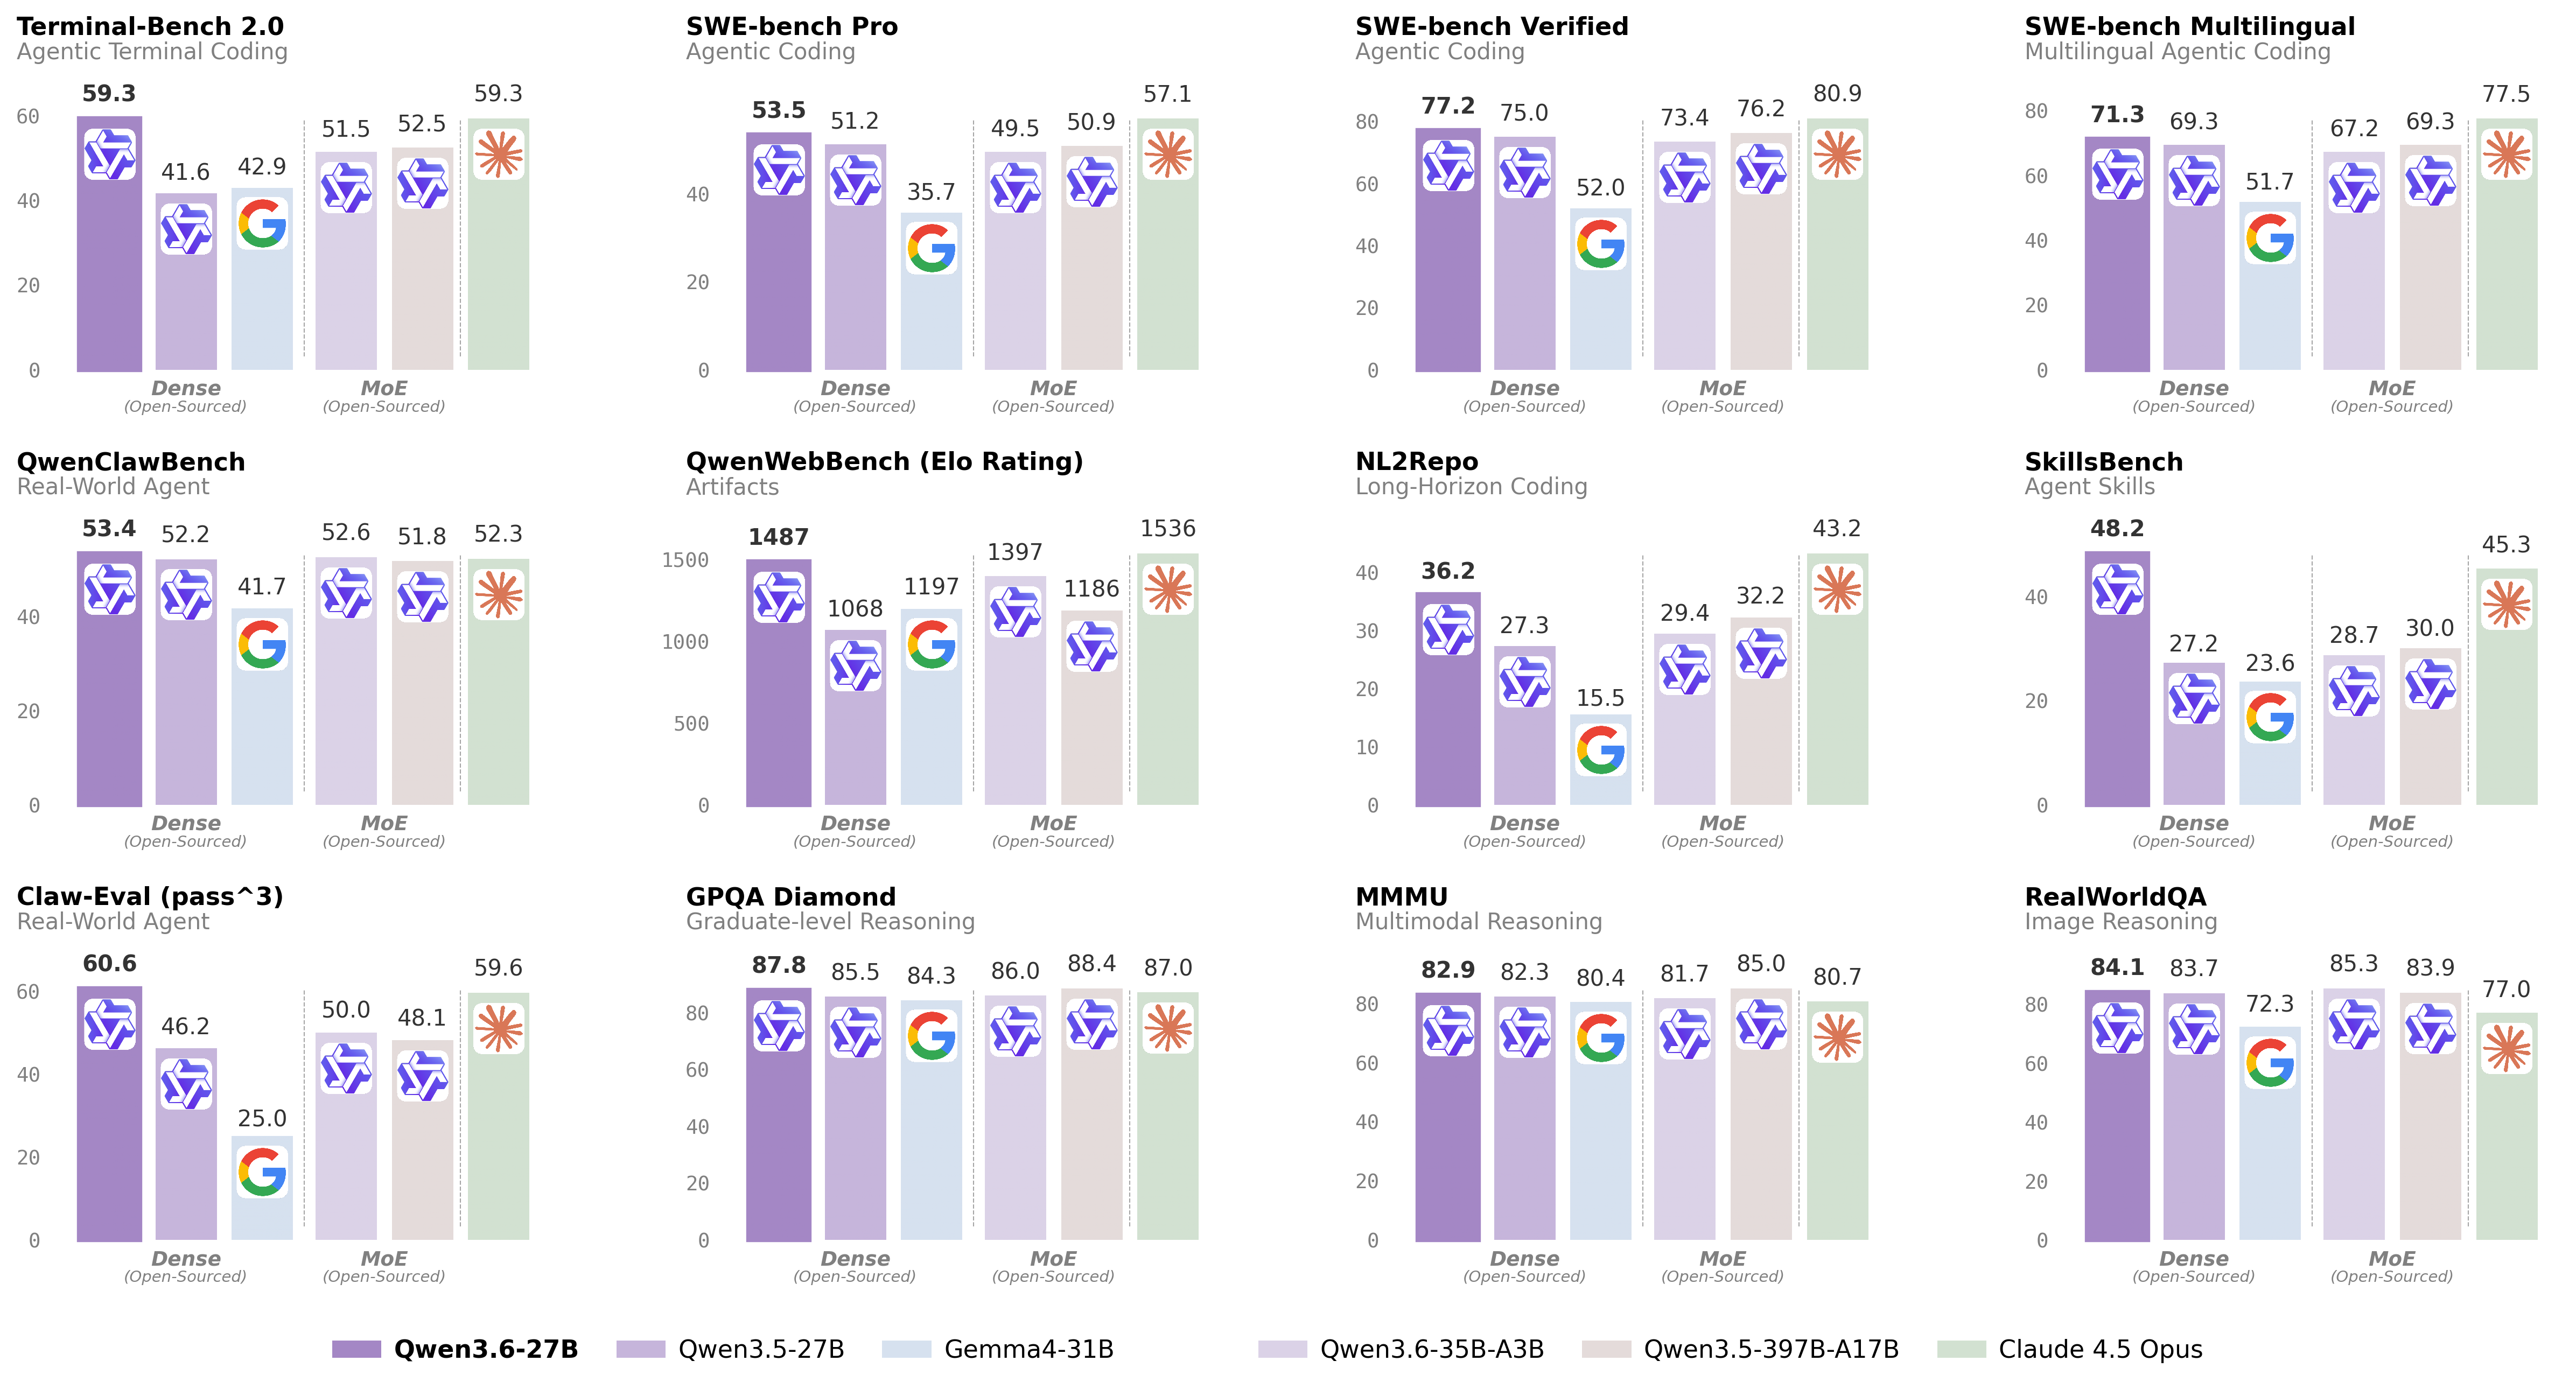
qwen3.6-27b-nvfp4-mtp
# Qwen3.6-27B
[](https://chat.qwen.ai)
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
## Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- **Agentic Coding:** the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- **Thinking Preservation:** we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post Qwen3.6-27B.
## Model Overview
...
Repository: localai
qwen3.6-27b-nvfp4-vllm-cpp
Qwen3.6-27B in NVFP4, served by vllm.cpp: LocalAI's own C++ port of vLLM, with
no Python at inference time. This is the reference text-generation checkpoint
the engine is gated on, token-for-token identical to vLLM's own greedy output
over the 235-prompt correctness battery, and measured at or above vLLM's
throughput at every concurrency from 1 to 32.
The weights are PINNED to revision 890bdef7. That pin is load-bearing, not
housekeeping: the same repository name was later re-quantized to FP8 W8A8
throughout, so an unpinned copy of this entry serves entirely different
weights with no error and none of the measured behaviour above.
Needs a Blackwell-class NVIDIA GPU (NVFP4 has no kernel on older
architectures) and roughly 25 GB of weights plus KV cache. Tool calling and
the thinking split are parsed inside the engine.
Repository: localaiLicense: apache-2.0
qwen3.6-27b-nvfp4-mtp-vllm-cpp
Qwen3.6-27B NVFP4 on vllm.cpp with MTP speculative decoding enabled.
MTP (Multi-Token Prediction) drafts from a head that ships inside the target
checkpoint's own mtp.* tensors, so there is no second model to download and
no extra weights to manage. The verifier accepts roughly 85% of drafted
tokens on prose and 92% on code, worth about 1.5x to 1.6x the decode
throughput of the same weights with speculation off, and it holds that lead
at concurrency 2, 4 and 8.
Same weights and same revision pin as qwen3.6-27b-nvfp4-vllm-cpp; install
that entry instead if you would rather not spend the extra memory. The
speculative state (a doubled recurrent-state slot plus the draft cache and
head) costs roughly 3.6 GB on top of the base footprint.
MTP here is depth 1 by construction: the engine refuses
num_speculative_tokens above 1 for this method.
Repository: localaiLicense: apache-2.0
qwen3.6-27b-nvfp4-dflash-vllm-cpp
Qwen3.6-27B NVFP4 on vllm.cpp with DFlash block-diffusion speculative
decoding: the fastest configuration of this model the engine ships.
Where MTP drafts one token at a time, DFlash drafts a whole 16-token block in
a single non-autoregressive pass from a separate 3.5 GB drafter, then the
target verifies the block in one step. At concurrency 1 that measures 2.9x
the throughput of the same weights with speculation off, and at or above
vLLM's own DFlash-on decode.
Both checkpoints are installed for you: the target as a revision-pinned
snapshot, the drafter into models/Qwen3.6-27B-DFlash, which is where the
backend looks when speculative_config.model names it. The drafter shares the
target's embed_tokens and lm_head, so the two are not independently
swappable.
Needs a Blackwell-class NVIDIA GPU and roughly 28 GB of weights in total.
Repository: localaiLicense: apache-2.0
qwen3.6-35b-a3b-nvfp4-vllm-cpp
Qwen3.6-35B-A3B in NVFP4, served by vllm.cpp. A 35B mixture-of-experts model
with roughly 3B parameters active per token, so it reads like a much larger
model while costing about as much per token as a small one.
Image input is implemented in the engine but is not token-gated against
vLLM yet, so the vision usecase on this entry is experimental.
This is the engine's gated MoE checkpoint: token-for-token identical to vLLM
over the 315-prompt battery on both the synchronous and asynchronous paths,
at 0.92x to 0.97x vLLM's throughput from concurrency 1 to 32.
The architecture is a gated-delta-net hybrid, so automatic prefix caching is
off by default here where it would be on for a dense model. That is the
engine's own default and this entry does not override it.
Needs a Blackwell-class NVIDIA GPU and roughly 23 GB of weights plus KV cache.
Repository: localaiLicense: apache-2.0
qwen3.6-35b-a3b-nvfp4-mtp-vllm-cpp
Qwen3.6-35B-A3B NVFP4 on vllm.cpp with MTP speculative decoding enabled.
Image input is implemented in the engine but is not token-gated against
vLLM yet, so the vision usecase on this entry is experimental.
The draft head ships inside the checkpoint's own mtp.* tensors, so there is
no second model to download. On this model the speculative path is
token-exact against speculation-off on both the synchronous and asynchronous
schedulers.
Same weights as qwen3.6-35b-a3b-nvfp4-vllm-cpp; install that entry instead if
you would rather not spend the extra memory on speculative state. MTP is
depth 1 by construction on this engine.
Repository: localaiLicense: apache-2.0

minimax-h3-fl2va-pruned-nvfp4
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: fl2va. DiT layout:
pruned. Format: NVFP4.
This entry is the FL2VA partition, which serves text-to-video (t2va) and first/last-frame conditioning (fl2va). It refuses reference conditioning: for that use the matching ref2va entry. The DiT is the pruned DiT (AdaLN curve table in place of the per-block modulation projection; about 20B instead of 33B parameters) (~12.5 GB).
Render status: loads, not rendered (vllm.cpp model page: NVFP4 exists and loads, pruned
and unpruned). The quantised weights stay resident; nothing here expands them.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
qwen-image-2.1-text-encoder-heretic
> 🍱 **All-GGUF Qwen-Image-2.1:** text encoder GGUF + DiT GGUF (Q8_0 / Q6_K / Q4_K_M, loads in stock ComfyUI-GGUF) + PE-T2I GGUF.
> [!IMPORTANT]
> **The 4 `model-0000x-of-00004` shards are the HF `transformers` checkpoint (bf16) — they do not load in ComfyUI.**
> ComfyUI text encoders use a different key layout (the `model.language_model.` prefix is dropped
> when repacking), so pointing ComfyUI at these shards will not work.
>
> For ComfyUI use one of these instead — all keep the vision tower, which 2.1 needs for editing.
> **Mac / non-CUDA:** use the single file `qwen3vl_8b_bf16_heretic.safetensors` in *this* repo (full bf16, 17.5 GB — also in the GGUF repo) —
> put it in `models/text_encoders/` and load it with the stock `CLIPLoader`, type `qwen_image`, then `TextEncodeQwenImage21`.
> It is the only format here that needs no CUDA-specific kernels.
>
> | Repo | File | Loader |
> |---|---|---|
> | **this repo** | `qwen3vl_8b_bf16_heretic.safetensors` (bf16 single file, any device) | `CLIPLoader`, type `qwen_image` |
> | `…-NVFP4` | `qwen3vl_8b_nvfp4_heretic.safetensors` | `CLIPLoader`, type `qwen_image` |
> | `…-W4A8` | `qwen3vl_8b_w4a8_heretic.safetensors` | `CLIPL
...
Repository: localaiLicense: apache-2.0