Filter by type:
Filter by tags:

Attention: Trust Remote Code is required for this model
wemm-embedding-2b
WeMM-Embedding-2B is Tencent's Apache-2.0 multilingual embedding model
built on Qwen3.5. This entry serves the original bfloat16 safetensors with
LocalAI's Transformers backend and produces 2,048-dimensional normalized
embeddings for text retrieval, semantic search, and RAG.
The upstream model can also embed images and videos. LocalAI currently
exposes text input through its embeddings API for this backend.
Repository: localaiLicense: apache-2.0
Attention: Trust Remote Code is required for this model
wemm-embedding-4b
WeMM-Embedding-4B is Tencent's mid-sized Apache-2.0 multilingual embedding
model built on Qwen3.5. This entry serves the original bfloat16 safetensors
with LocalAI's Transformers backend and produces 2,560-dimensional
normalized embeddings for text retrieval, semantic search, and RAG.
The upstream model can also embed images and videos. LocalAI currently
exposes text input through its embeddings API for this backend.
Repository: localaiLicense: apache-2.0
Attention: Trust Remote Code is required for this model
wemm-embedding-9b
WeMM-Embedding-9B is Tencent's largest Apache-2.0 multilingual embedding
model built on Qwen3.5. This entry serves the original bfloat16 safetensors
with LocalAI's Transformers backend and produces 4,096-dimensional
normalized embeddings for text retrieval, semantic search, and RAG.
The upstream model can also embed images and videos. LocalAI currently
exposes text input through its embeddings API for this backend.
Repository: localaiLicense: apache-2.0

qwen3.8-27b-obliterated-q4
Qwen3.8-27B OBLITERATED is an Apache-2.0 Qwen3.8 vision-language model
modified for refusal-removal and red-team research. It retains reasoning,
coding, tool use, image, and video capabilities, but its safety guardrails
have been removed.
This default entry uses the Q4_K_M GGUF and BF16 vision projector. The
linked variant uses the higher-quality Q8_0 model. The publisher recommends
greedy decoding with a 1.15 repetition penalty.
Repository: localaiLicense: apache-2.0
qwen3.8-27b-q4
Qwen3.8-27B is Qwen's dense 27B vision-language model for reasoning,
coding, tool use, and long-running agent tasks. It accepts text, images,
and video, and it supports a native context window of 262K tokens.
This default entry uses the official Q4_K_M GGUF and Q8_0 vision
projector. The linked variants add MTP speculative decoding or use the
higher-quality Q8_0 model.
Repository: localaiLicense: apache-2.0
qwen3.5-9b-hauhaucs-aggressive
Qwen3.5 9B Aggressive is HauhauCS's refusal-removed fine-tune of the
multimodal Qwen3.5 9B model. It retains the base model's reasoning, tool
use, image and video understanding, and 262K-token native context window.
This entry uses the balanced Q4_K_M GGUF quantization and includes the
matching BF16 multimodal projector. The Q8_0 variant offers higher fidelity.
Repository: localaiLicense: apache-2.0
qwen3.5-9b-hauhaucs-aggressive-q8
Qwen3.5 9B Aggressive is HauhauCS's refusal-removed fine-tune of the
multimodal Qwen3.5 9B model. It retains the base model's reasoning, tool
use, image and video understanding, and 262K-token native context window.
This entry uses the higher-fidelity Q8_0 GGUF quantization and includes the
matching BF16 multimodal projector.
Repository: localaiLicense: apache-2.0
gemma-4-12b-agentic-fable5-composer2.5-v2-3.5x-tau2
Hugging Face |
GitHub |
Launch Blog |
Documentation
License: Apache 2.0 | Authors: Google DeepMind
> [!Note]
> This model card is for the Gemma 4 12B Unified model, which is part of the Gemma 4 family of open models. Built with the same multimodal functionality as Gemma 4 E2B and E4B (text, audio, image, and video inputs), it brings native audio and vision understanding directly to local environments without the need for separate encoders. This unified approach to multimodality makes the model encoder-free, offering a deployment size that is perfect for consumer devices and streamlined local execution.
Gemma is a family of open models built by Google DeepMind. Gemma 4 models are multimodal, handling text and image input (with audio supported on E2B, E4B, and 12B) and generating text output. This release includes open-weights models in both pre-trained and instruction-tuned variants. Gemma 4 features a context window of up to 256K tokens and maintains multilingual support in over 140 languages.
...
Repository: localaiLicense: apache-2.0
gemma-4-12b-coder-fable5-composer2.5-v1
Hugging Face |
GitHub |
Launch Blog |
Documentation
License: Apache 2.0 | Authors: Google DeepMind
> [!Note]
> This model card is for the Gemma 4 12B Unified model, which is part of the Gemma 4 family of open models. Built with the same multimodal functionality as Gemma 4 E2B and E4B (text, audio, image, and video inputs), it brings native audio and vision understanding directly to local environments without the need for separate encoders. This unified approach to multimodality makes the model encoder-free, offering a deployment size that is perfect for consumer devices and streamlined local execution.
Gemma is a family of open models built by Google DeepMind. Gemma 4 models are multimodal, handling text and image input (with audio supported on E2B, E4B, and 12B) and generating text output. This release includes open-weights models in both pre-trained and instruction-tuned variants. Gemma 4 features a context window of up to 256K tokens and maintains multilingual support in over 140 languages.
...
Repository: localaiLicense: gemma

nemotron-3-nano-omni-30b-a3b-reasoning-apex
# Model Overview
### Description:
NVIDIA Nemotron 3 Nano Omni is a multimodal large language model that unifies video, audio, image, and text understanding to support enterprise-grade Q&A, summarization, transcription, and document intelligence workflows. It extends the Nemotron Nano family with integrated video+speech comprehension, Graphical User Interface (GUI), Optical Character Recognition (OCR), and speech transcription capabilities, enabling end-to-end processing of rich enterprise content such as meeting recordings, M&E assets, training videos, and complex business documents. NVIDIA Nemotron 3 Nano Omni was developed by NVIDIA as part of the Nemotron model family.
This model is available for commercial use.
This model was improved using Qwen3-VL-30B-A3B-Instruct, Qwen3.5-122B-A10B, Qwen3.5-397B-A17B, Qwen2.5-VL-72B-Instruct, and gpt-oss-120b. For more information, please see the Training Dataset section below.
### License/Terms of Use
Governing Terms: Use of this model is governed by the NVIDIA Open Model Agreement
### Deployment Geography:
Global
...
Repository: localaiLicense: other
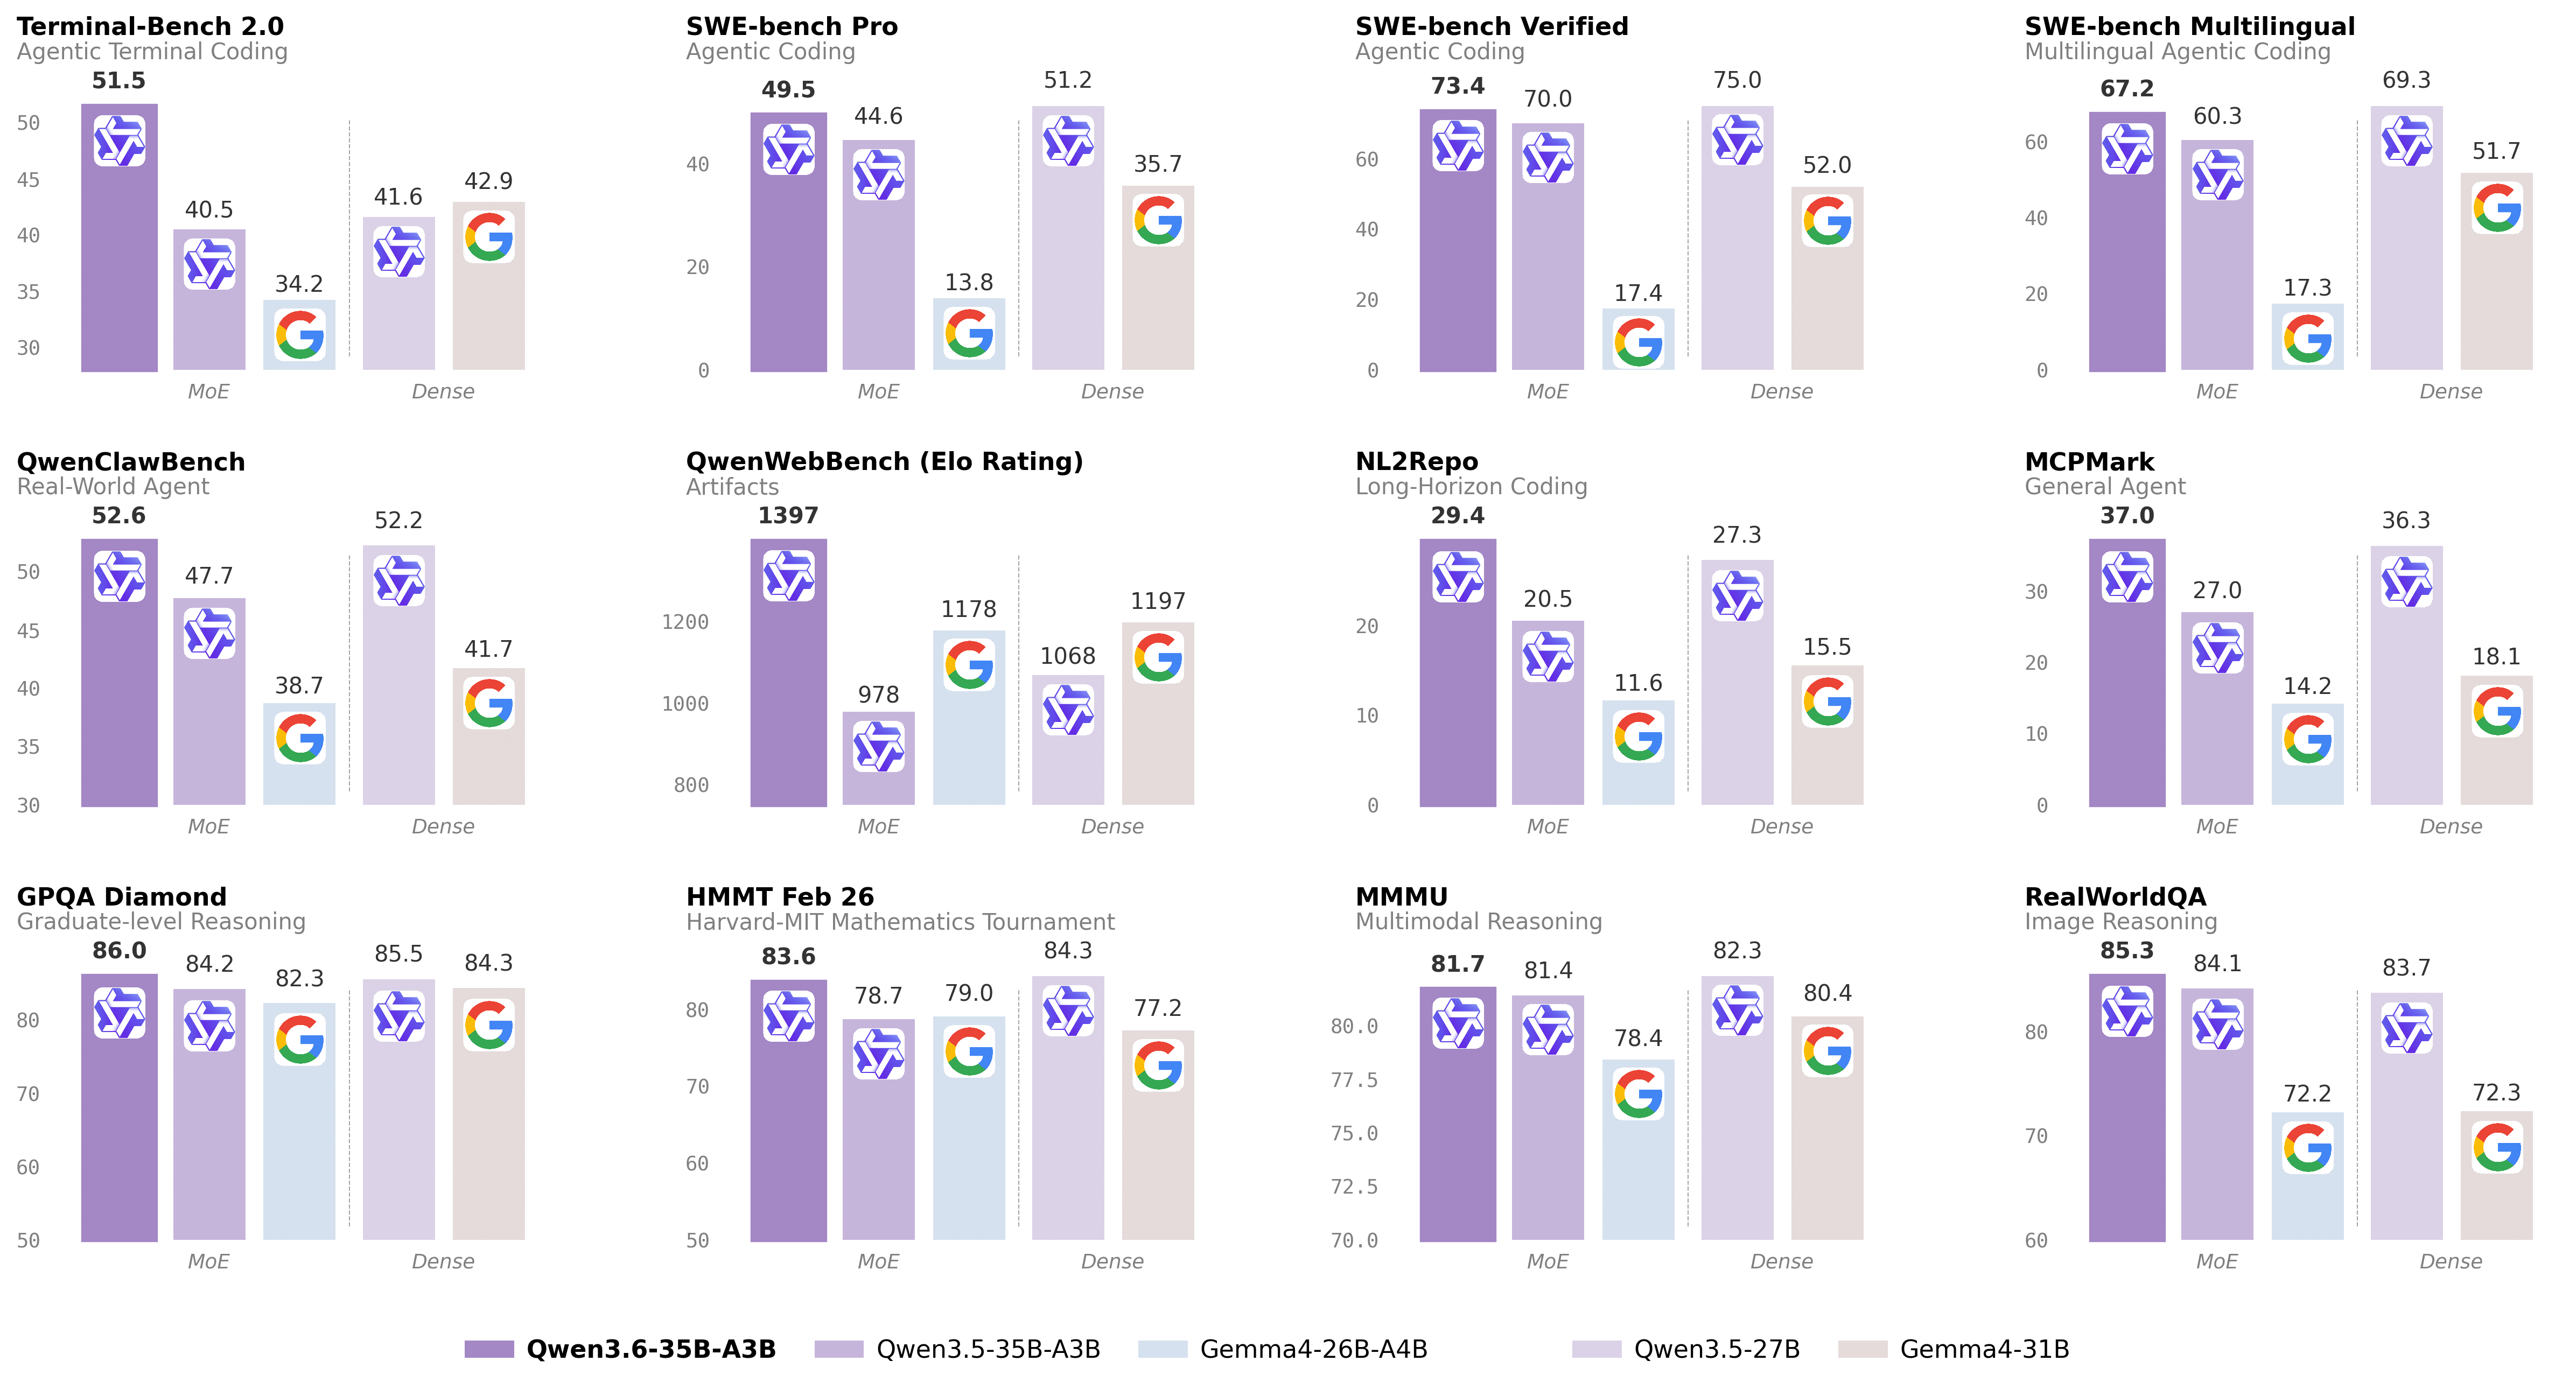
qwen3.6-35b-a3b-claude-4.6-opus-reasoning-distilled
# 🔥 Qwen3.6-35B-A3B-Claude-4.6-Opus-Reasoning-Distilled
A reasoning SFT fine-tune of `Qwen/Qwen3.6-35B-A3B` on chain-of-thought (CoT) distillation mostly sourced from Claude Opus 4.6. The goal is to preserve Qwen3.6's strong agentic coding and reasoning base while nudging the model toward structured Claude Opus-style reasoning traces and more stable long-form problem solving.
The training path is text-only. The Qwen3.6 base architecture includes a vision encoder, but this fine-tuning run did not train on image or video examples.
- **Developed by:** @hesamation
- **Base model:** `Qwen/Qwen3.6-35B-A3B`
- **License:** apache-2.0
This fine-tuning run is inspired by Jackrong/Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled, including the notebook/training workflow style and Claude Opus reasoning-distillation direction.
[](https://x.com/Hesamation) [](https://discord.gg/vtJykN3t)
## Benchmark Results
The MMLU-Pro pass used 70 total questions per model: `--limit 5` across 14 MMLU-Pro subjects. Treat this as a smoke/comparative check, not a release-quality full benchmark.
...
Repository: localaiLicense: apache-2.0

vllm-omni-wan2.2-t2v
Wan2.2-T2V-A14B via vLLM-Omni - Text-to-video generation model from Wan-AI. Generates high-quality videos from text prompts using a 14B parameter diffusion model.
Repository: localaiLicense: apache-2.0
vllm-omni-wan2.2-i2v
Wan2.2-I2V-A14B via vLLM-Omni - Image-to-video generation model from Wan-AI. Generates high-quality videos from images using a 14B parameter diffusion model.
Repository: localaiLicense: apache-2.0
longcat-video
LongCat-Video served by LocalAI's dedicated CUDA backend. Generates video
from a text prompt or a start image. The SDPA attention path works without
FlashAttention and is suitable for CUDA 13 ARM64 systems such as DGX Spark.
This is a very large checkpoint (roughly 83 GB in Hugging Face storage) and
requires Linux with an NVIDIA CUDA GPU plus substantial memory and disk.
Repository: localaiLicense: mit
longcat-video-avatar-1.5
LongCat-Video-Avatar-1.5 served by LocalAI's dedicated CUDA backend. Turns
speech plus a prompt into an avatar video, optionally conditioning on a
portrait, and continues across multiple segments for longer audio.
Avatar generation also loads tokenizer, text encoder, and VAE components
from LongCat-Video. Plan for very large downloads and substantial NVIDIA
GPU or unified memory; CPU and macOS execution are unsupported.
Repository: localaiLicense: mit

minimax-h3-fl2va-unpruned-q4
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: fl2va. DiT layout:
unpruned. Format: Q4_K_M.
This entry is the FL2VA partition, which serves text-to-video (t2va) and first/last-frame conditioning (fl2va). It refuses reference conditioning: for that use the matching ref2va entry. The DiT is the original time-embedder DiT (~19.9 GB).
Render status: verified render (end to end on the vllm.cpp model page).
Q3_K_M of the same DiT is verified BAD and is not offered.
The vllm.cpp page records its renders with the DiT expanded to bf16. This
entry does not expand it and keeps the quantised weights resident, so a
render in that mode is not covered by the page.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
minimax-h3-fl2va-q4
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: fl2va. DiT layout:
unpruned. Format: Q4_K_M.
This entry is the FL2VA partition, which serves text-to-video (t2va) and first/last-frame conditioning (fl2va). It refuses reference conditioning: for that use the matching ref2va entry. The DiT is the original time-embedder DiT (~19.9 GB).
Render status: verified render (end to end on the vllm.cpp model page).
Q3_K_M of the same DiT is verified BAD and is not offered.
The vllm.cpp page records its renders with the DiT expanded to bf16. This
entry does not expand it and keeps the quantised weights resident, so a
render in that mode is not covered by the page.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
minimax-h3-ref2va-unpruned-q4
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: ref2va. DiT layout:
unpruned. Format: Q4_K_M.
This entry is the Ref2VA partition, which takes REFERENCE conditioning (reference images, clips and audio) so the subject or voice carries into the clip. It refuses plain text-to-video and first/last-frame requests: for those use the matching fl2va entry. The DiT is the original time-embedder DiT (~19.9 GB).
Render status: verified render (end to end on the vllm.cpp model page).
Do NOT use the NVFP4 Ref2VA weights: they render a multicolour patch grid.
Q3_K_M of the same DiT is verified BAD and is not offered.
The vllm.cpp page records its renders with the DiT expanded to bf16. This
entry does not expand it and keeps the quantised weights resident, so a
render in that mode is not covered by the page.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
minimax-h3-ref2va-q4
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: ref2va. DiT layout:
unpruned. Format: Q4_K_M.
This entry is the Ref2VA partition, which takes REFERENCE conditioning (reference images, clips and audio) so the subject or voice carries into the clip. It refuses plain text-to-video and first/last-frame requests: for those use the matching fl2va entry. The DiT is the original time-embedder DiT (~19.9 GB).
Render status: verified render (end to end on the vllm.cpp model page).
Do NOT use the NVFP4 Ref2VA weights: they render a multicolour patch grid.
Q3_K_M of the same DiT is verified BAD and is not offered.
The vllm.cpp page records its renders with the DiT expanded to bf16. This
entry does not expand it and keeps the quantised weights resident, so a
render in that mode is not covered by the page.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
minimax-h3-fl2va-pruned-q8
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: fl2va. DiT layout:
pruned. Format: Q8_0.
This entry is the FL2VA partition, which serves text-to-video (t2va) and first/last-frame conditioning (fl2va). It refuses reference conditioning: for that use the matching ref2va entry. The DiT is the pruned DiT (AdaLN curve table in place of the per-block modulation projection; about 20B instead of 33B parameters) (~21.4 GB).
Render status: loads and renders (vllm.cpp model page, pruned Q8_0 A/B).
The vllm.cpp page records its renders with the DiT expanded to bf16. This
entry does not expand it and keeps the quantised weights resident, so a
render in that mode is not covered by the page.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
minimax-h3-fl2va-pruned-q6
MiniMax-H3 served by vllm.cpp, LocalAI's own C++ port of vLLM. It generates
video AND audio jointly, so a clip comes back as an MP4 with a soundtrack.
Ask for speech in the prompt and the model lip-syncs it.
Runtime: vllm.cpp (backend vllm-cpp). Partition: fl2va. DiT layout:
pruned. Format: Q6_K.
This entry is the FL2VA partition, which serves text-to-video (t2va) and first/last-frame conditioning (fl2va). It refuses reference conditioning: for that use the matching ref2va entry. The DiT is the pruned DiT (AdaLN curve table in place of the per-block modulation projection; about 20B instead of 33B parameters) (~16.6 GB).
Render status: loads, not rendered. The vllm.cpp model page says the pruned Q6_K file loads through the same path as Q8_0; only Q8_0 has been rendered.
The vllm.cpp page records its renders with the DiT expanded to bf16. This
entry does not expand it and keeps the quantised weights resident, so a
render in that mode is not covered by the page.
The weights are one DiT, the Qwen3-VL-32B encoder (~14.6 GB), the video VAE
(~10.4 GB), the audio VAE and the tokenizer, plus the two VAE configs that
carry the latent statistics. The default canvas is 1344x768 at 124 frames
and 24 fps, about 5.2 seconds. Generation is slow: roughly 176 s per denoise
step at that canvas on a 20-SM device. Muxing the finished frames needs
ffmpeg on the host.
Repository: localaiLicense: other
Page 1