Filter by type:
Filter by tags:

ternary-bonsai-2-2b
Ternary Bonsai 2 2B is a vision-language model derived from Qwen3.5-2B
with ternary transformer weights. This PQ2_0 build uses the Bonsai
backend and includes the Q8_0 vision projector. The three standard
packings contain the same weights in different storage layouts.
Repository: localaiLicense: apache-2.0
ternary-bonsai-2-2b-ptq1
Ternary Bonsai 2 2B is a vision-language model derived from Qwen3.5-2B
with ternary transformer weights. This PTQ1_0 build uses the Bonsai
backend and includes the Q8_0 vision projector. The three standard
packings contain the same weights in different storage layouts.
Repository: localaiLicense: apache-2.0
ternary-bonsai-2-2b-q2
Ternary Bonsai 2 2B is a vision-language model derived from Qwen3.5-2B
with ternary transformer weights. This Q2_0 build uses the Bonsai
backend and includes the Q8_0 vision projector. The three standard
packings contain the same weights in different storage layouts.
Repository: localaiLicense: apache-2.0
ternary-bonsai-2-9b
Ternary Bonsai 2 9B is a vision-language model derived from Qwen3.5-9B
with ternary transformer weights. This PQ2_0 build uses the Bonsai
backend and includes the Q8_0 vision projector. The three standard
packings contain the same weights in different storage layouts.
Repository: localaiLicense: apache-2.0
ternary-bonsai-2-9b-ptq1
Ternary Bonsai 2 9B is a vision-language model derived from Qwen3.5-9B
with ternary transformer weights. This PTQ1_0 build uses the Bonsai
backend and includes the Q8_0 vision projector. The three standard
packings contain the same weights in different storage layouts.
Repository: localaiLicense: apache-2.0
ternary-bonsai-2-9b-q2
Ternary Bonsai 2 9B is a vision-language model derived from Qwen3.5-9B
with ternary transformer weights. This Q2_0 build uses the Bonsai
backend and includes the Q8_0 vision projector. The three standard
packings contain the same weights in different storage layouts.
Repository: localaiLicense: apache-2.0
hy4-preview
# Hy4-preview GGUF
Three GGUF builds of Hy4-Preview: https://huggingface.co/tencent/Hy4-preview
**Language / 语言:** English · 中文
**Neither file runs on stock llama.cpp.** The `hyv4` architecture is not upstream. Apply the
patches in `hy4-preview-patch/`
## English
### 1. What these are
**`Hy4-preview-Q4_K_M.gguf`** — a conventional Q4_K_M. Most tensors are Q4_K; `ffn_down_exps`
gets Q6_K on 37 layers via llama.cpp's own logic. Use this unless you are memory-constrained.
**`Hy4-preview-UD-IQ1_M.gguf`** - mixed precision with UD-IQ1_M strategy at ~2.44 bpw, roughly **half the size** for the
same model. The routed-expert `gate`/`up` projections run at 1.75 bpw (IQ1_M) and 2.0625 bpw (IQ2_XXS).
**`Hy4-preview-STQ1_0.gguf`** — mixed precision with MIX-STQ1_0 strategy at ~2.38 bpw, roughly **half the size** for the
same model. The routed-expert `gate`/`up` projections run at 1.3125 bpw (STQ1_0) on 29 layers and
2.0625 bpw (IQ2_XXS) on the other 48. See section 3.
### 2. Running them
Build a patched llama.cpp
```bash
git clone https://github.com/ggml-org/llama.cpp && cd llama.cpp
git checkout 0cea36222
...
Repository: localai
glm-5.3
# GLM-5.3
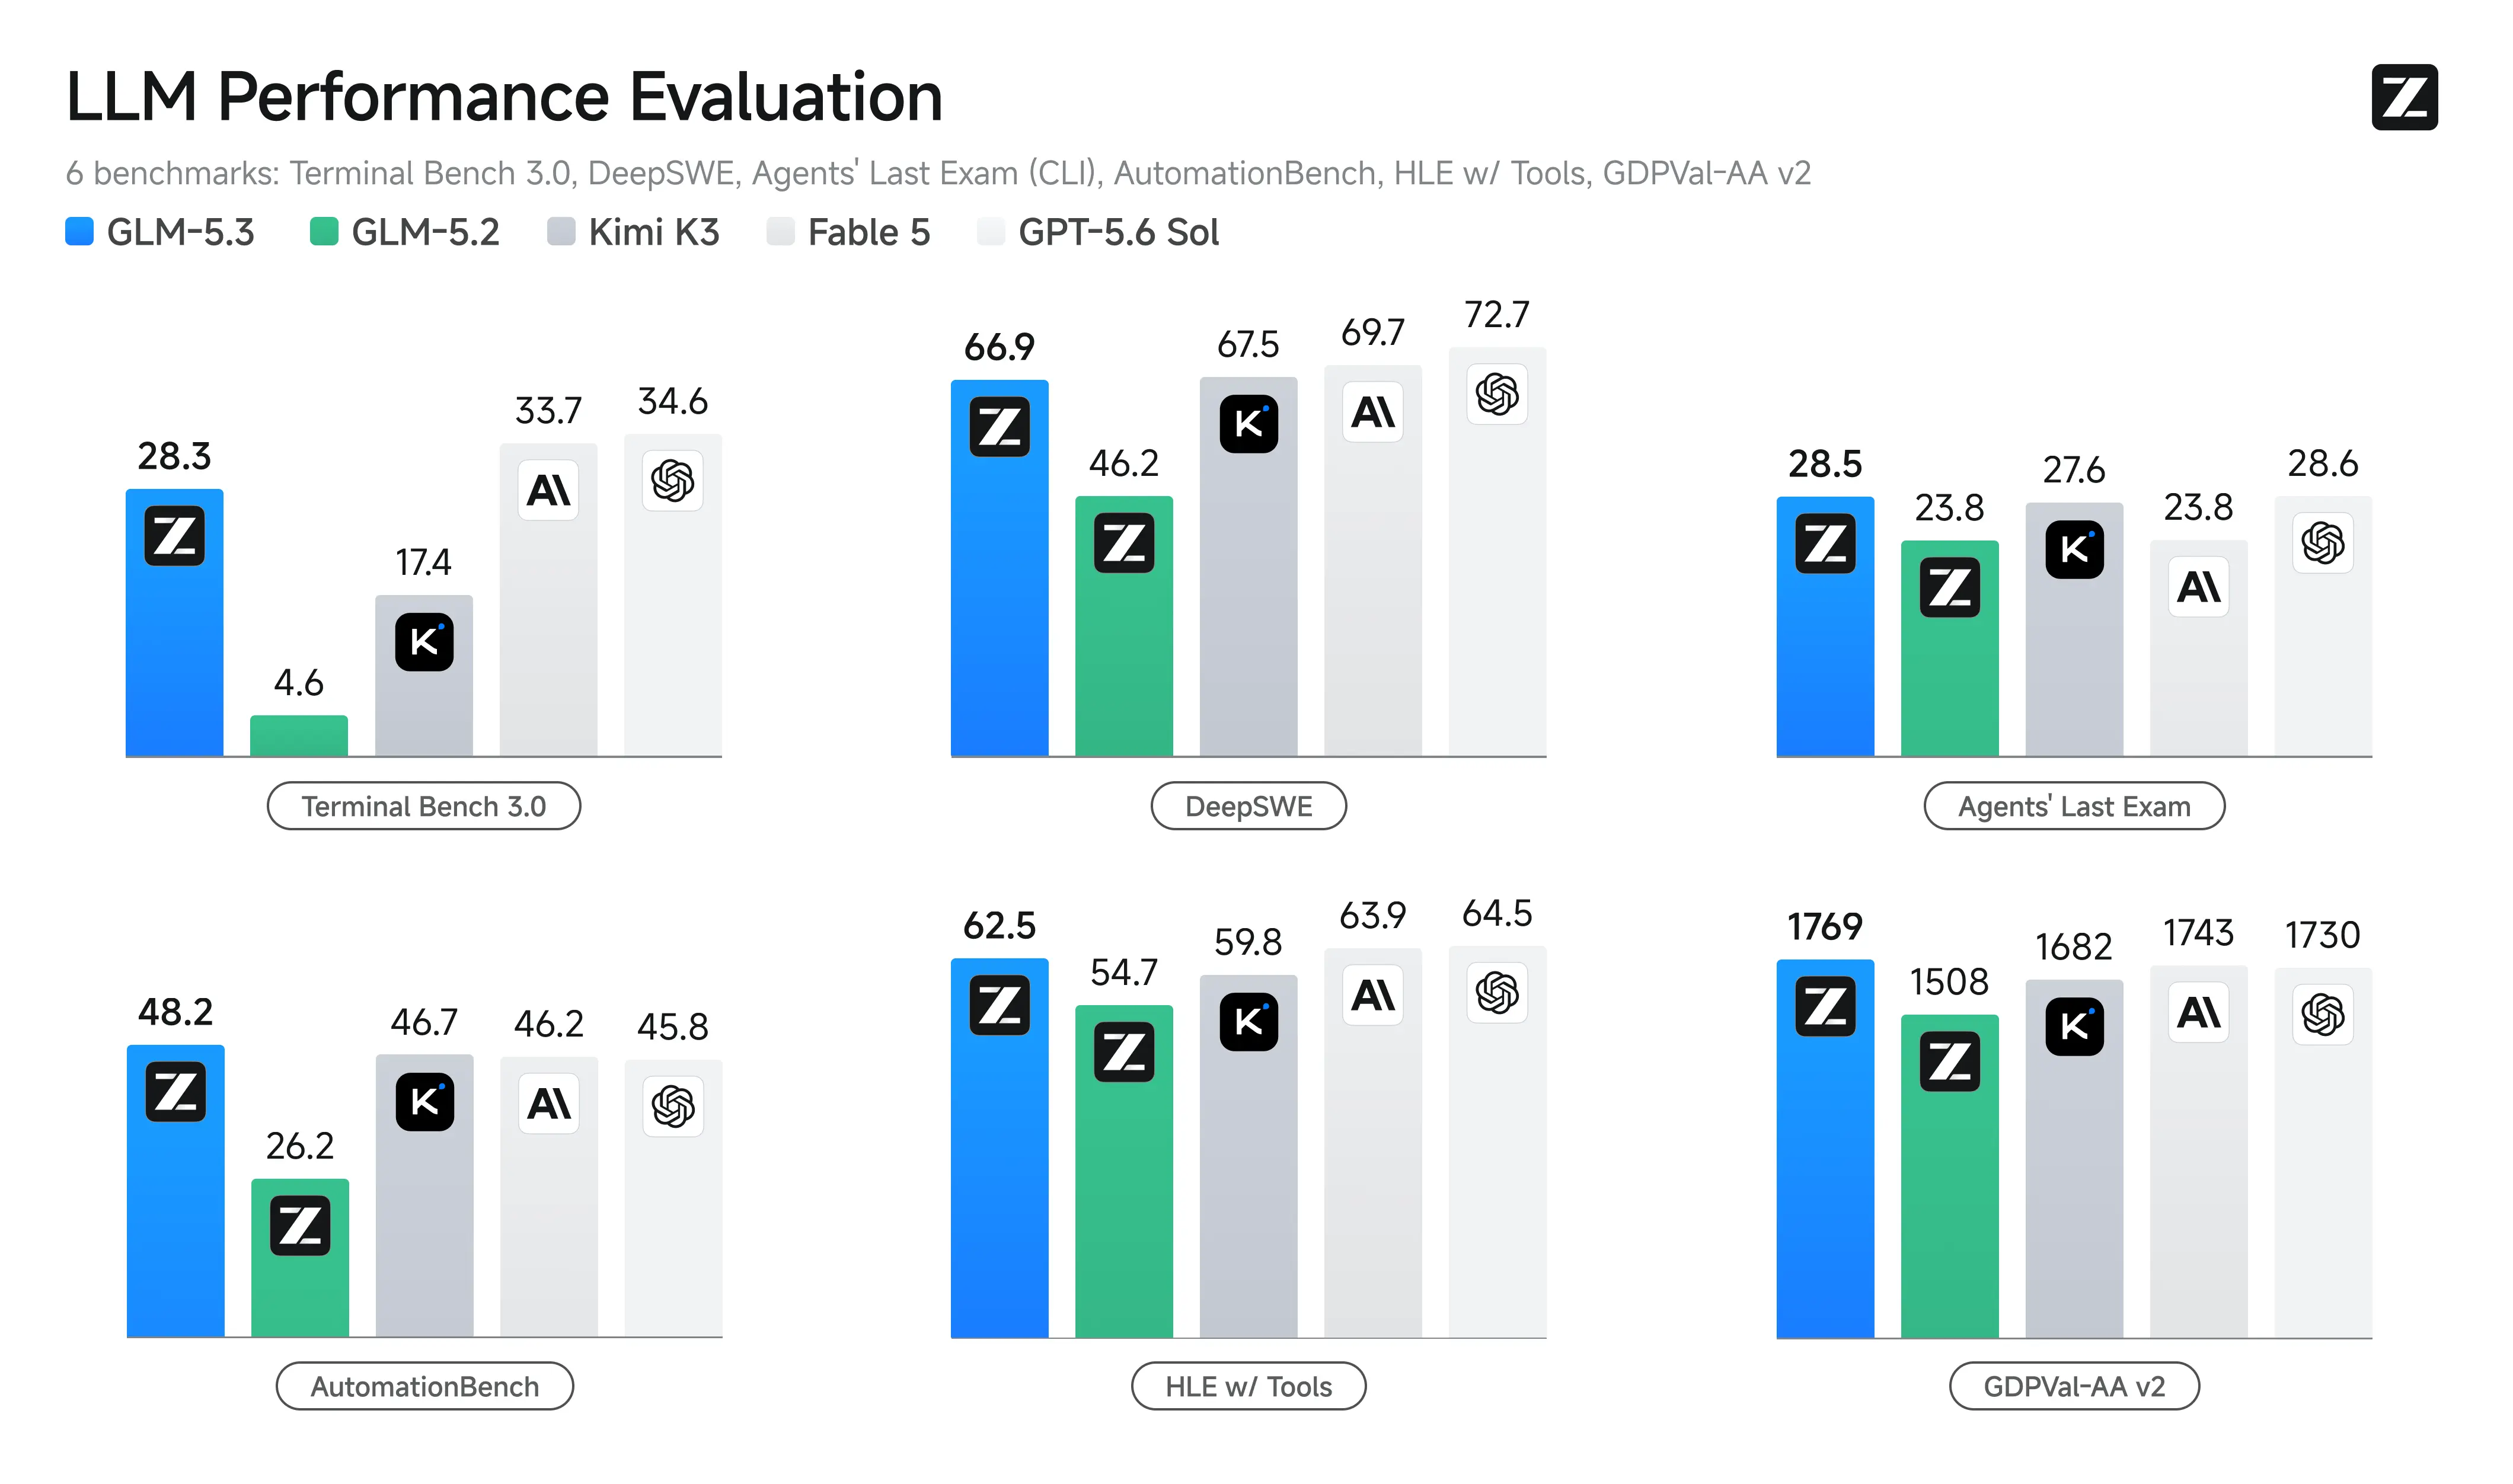
GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks:
+ Stronger Coding: GLM-5.3 is the most capable open-weights model for coding, with a 50% improvement over GLM-5.2 on our in-house Z.ai Code Bench. It also achieve open-source SOTA on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam.
+ Emergent Cyber Capability: As we scaled post-training, cyber capability developed faster than we expected. GLM-5.3 is state of the art on CyberGym for vulnerability discovery, and its gains are largest further up the exploitation chain, where it more than doubles GLM-5.2 on exploitation benchmarks.
## Benchmark
### Serve GLM-5.3 Locally
GLM-5.3 supports deployment with the following frameworks. Feel free to try them out:
- SGLang — see cookbook
- vLLM — see recipes
- TokenSpeed — see here
- Transformers — see transformers docs
- KTransformers — see tutorial
- Unsloth — see guide
- For deployment on the `Ascend NPU` platform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — see here.
### Note
...
Repository: localaiLicense: other
pocket-darwin-180b-q4
POCKET-Darwin-180B is a text-only reasoning model based on
Qwen3.8-Flash-Next. This UD-Q4_K_XL GGUF build uses llama.cpp and
downloads all four shards (about 111.3 GB). It uses the embedded
chat template, an 8192-token default context, and the publisher's
recommended sampling settings. Weights use Qwen Community License 1.0.
Repository: localaiLicense: other

qwen3.5-9b-defiant-fable
Qwen3.5 9B Defiant Fable in the plain NEO-imatrix Q4_K_M GGUF format.
This fallback offers the same multimodal reasoning, coding, and creative
capabilities without enabling multi-token prediction.
Repository: localaiLicense: apache-2.0

deepseek-v4-flash-0731
# DeepSeek-V4-Flash-0731
Technical Report👁️
## Introduction
**DeepSeek-V4-Flash-0731** is the official release of **DeepSeek-V4-Flash**, superseding the preview version, with substantially enhanced agentic capabilities. It has the same model structure as DeepSeek-V4-Flash-DSpark, i.e. it comes with a speculative decoding module attached.
DeepSeek-V4-Flash-0731 outperforms DeepSeek-V4-Pro (Preview) on benchmarks listed below despite its far smaller activated parameter count, and is broadly competitive with the strongest proprietary models available.
Notes:
1. For the Code Agent tasks among the public benchmarks above, DeepSeek-V4-Flash-0731 is evaluated with the minimal mode of DeepSeek Harness (to be released) as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`.
2. † DSBench-FullStack is an internal full-stack development test set; DSBench-Hard is an internal test set of difficult coding-agent problems.
## Chat Template
...
Repository: localaiLicense: mit
glm-5.2
# GLM-5.2
👋 Join our WeChat or Discord community.
📖 Check out the GLM-5.2 blog and GLM-5 Technical report.
📍 Use GLM-5.2 API services on Z.ai API Platform.
🔜 Try GLM-5.2 here.
[Paper]
[GitHub]
## Introduction
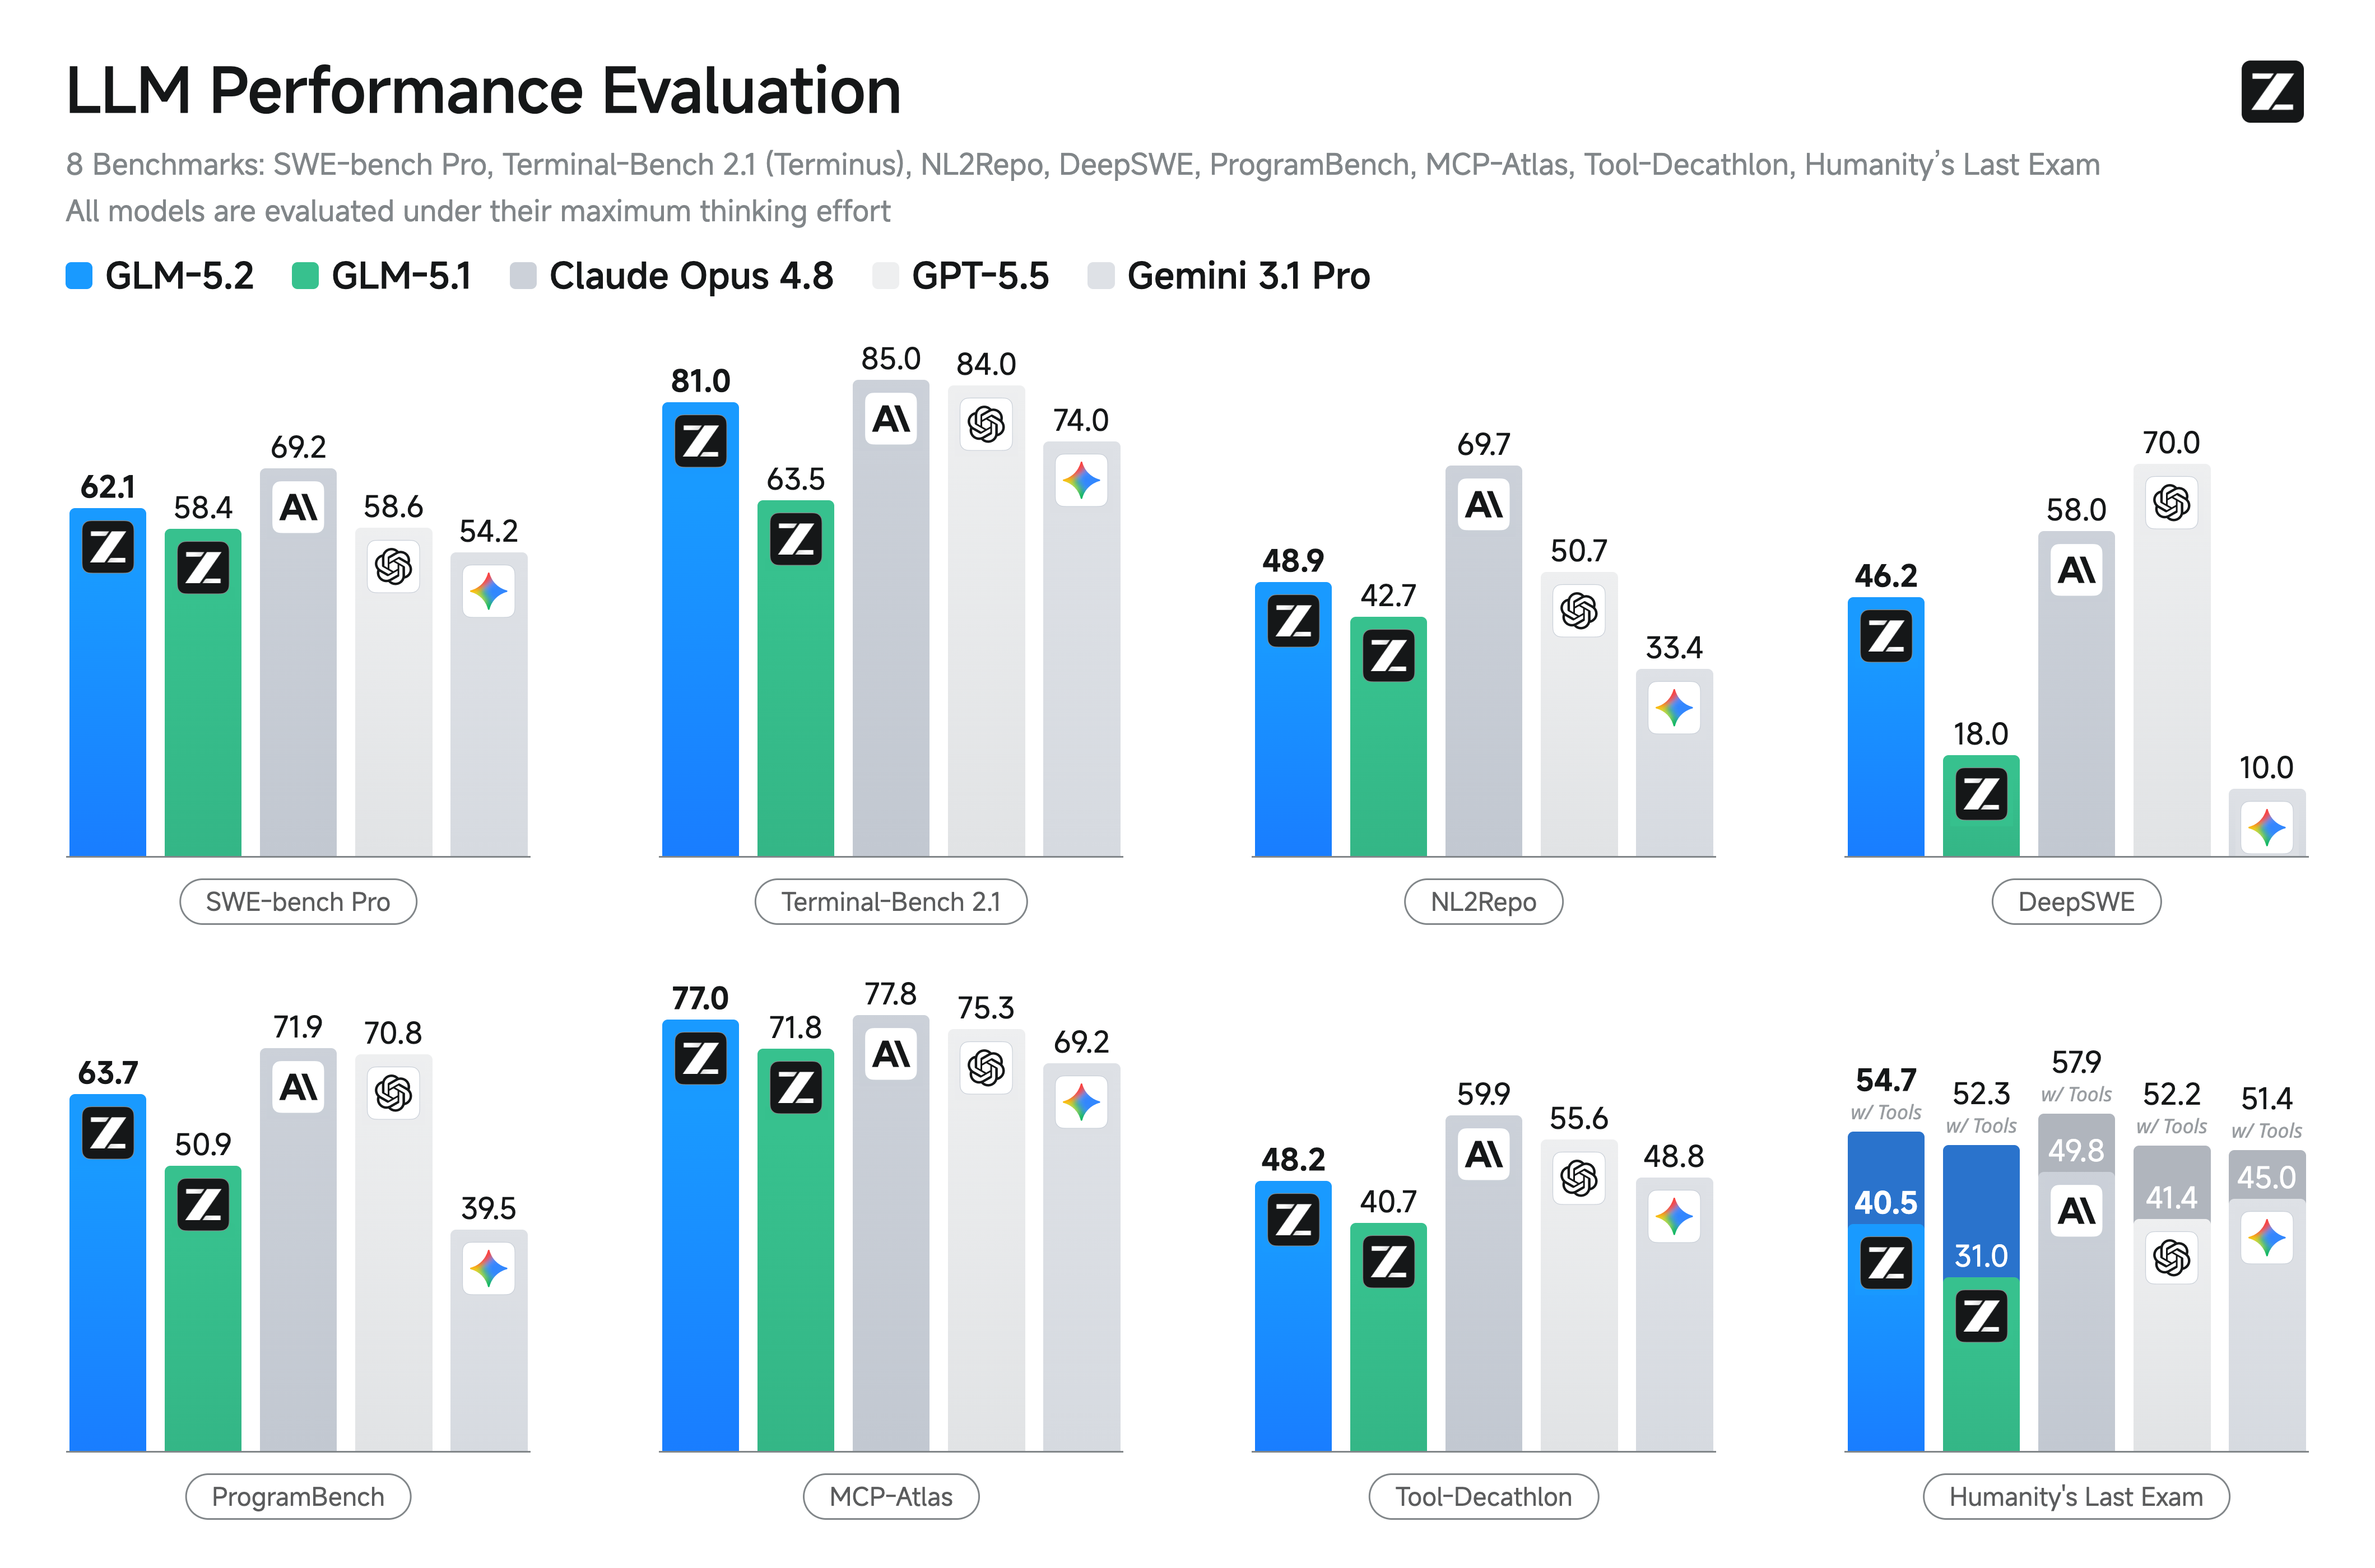
We're introducing GLM-5.2, our latest flagship model for long-horizon tasks. It marks a substantial leap in long-horizon task capability over its predecessor GLM-5.1 and, for the first time, delivers that capability on a **solid 1M-token context**. GLM-5.2's new capabilities include:
- **Solid 1M Context:** A solid 1M-token context that stably sustains long-horizon work
- **Advanced Coding with Flexible Effort**: Stronger coding capabilities with multiple thinking effort levels to balance performance and latency
- **Improved Architecture**: We propose IndexShare, which reuses the same indexer across every four sparse attention layers, reducing per-token FLOPs by 2.9× at a 1M context length. We also improve GLM-5.2’s MTP layer for speculative decoding, increasing the acceptance length by up to 20%
- **Pure Open**: An MIT open-source license — no regional limits, technical access without borders
## Benchmark
## Serve GLM-5.2 Locally
...
Repository: localaiLicense: mit
gemma-4-12b-agentic-fable5-composer2.5-v2-3.5x-tau2
Hugging Face |
GitHub |
Launch Blog |
Documentation
License: Apache 2.0 | Authors: Google DeepMind
> [!Note]
> This model card is for the Gemma 4 12B Unified model, which is part of the Gemma 4 family of open models. Built with the same multimodal functionality as Gemma 4 E2B and E4B (text, audio, image, and video inputs), it brings native audio and vision understanding directly to local environments without the need for separate encoders. This unified approach to multimodality makes the model encoder-free, offering a deployment size that is perfect for consumer devices and streamlined local execution.
Gemma is a family of open models built by Google DeepMind. Gemma 4 models are multimodal, handling text and image input (with audio supported on E2B, E4B, and 12B) and generating text output. This release includes open-weights models in both pre-trained and instruction-tuned variants. Gemma 4 features a context window of up to 256K tokens and maintains multilingual support in over 140 languages.
...
Repository: localaiLicense: apache-2.0
gemma-4-12b-coder-fable5-composer2.5-v1
Hugging Face |
GitHub |
Launch Blog |
Documentation
License: Apache 2.0 | Authors: Google DeepMind
> [!Note]
> This model card is for the Gemma 4 12B Unified model, which is part of the Gemma 4 family of open models. Built with the same multimodal functionality as Gemma 4 E2B and E4B (text, audio, image, and video inputs), it brings native audio and vision understanding directly to local environments without the need for separate encoders. This unified approach to multimodality makes the model encoder-free, offering a deployment size that is perfect for consumer devices and streamlined local execution.
Gemma is a family of open models built by Google DeepMind. Gemma 4 models are multimodal, handling text and image input (with audio supported on E2B, E4B, and 12B) and generating text output. This release includes open-weights models in both pre-trained and instruction-tuned variants. Gemma 4 features a context window of up to 256K tokens and maintains multilingual support in over 140 languages.
...
Repository: localaiLicense: gemma
gemma-4-e4b-hauhaucs-aggressive-q4
HauhauCS Aggressive is an uncensored derivative of Google's Gemma 4 E4B
instruction model. This Q4_K_M GGUF supports text chat and image input
through the publisher's bundled F16 multimodal projector.
Uses the embedded chat template and the publisher's sampling settings.
The default context is 8192 tokens. The publisher declares the Gemma license.
Repository: localaiLicense: gemma
gemma-4-e4b-hauhaucs-aggressive-q5
HauhauCS Aggressive is an uncensored derivative of Google's Gemma 4 E4B
instruction model. This Q5_K_M GGUF supports text chat and image input
through the publisher's bundled F16 multimodal projector.
Uses the embedded chat template and the publisher's sampling settings.
The default context is 8192 tokens. The publisher declares the Gemma license.
Repository: localaiLicense: gemma
qwen3.6-35b-a3b-claude-4.6-opus-reasoning-distilled
# 🔥 Qwen3.6-35B-A3B-Claude-4.6-Opus-Reasoning-Distilled
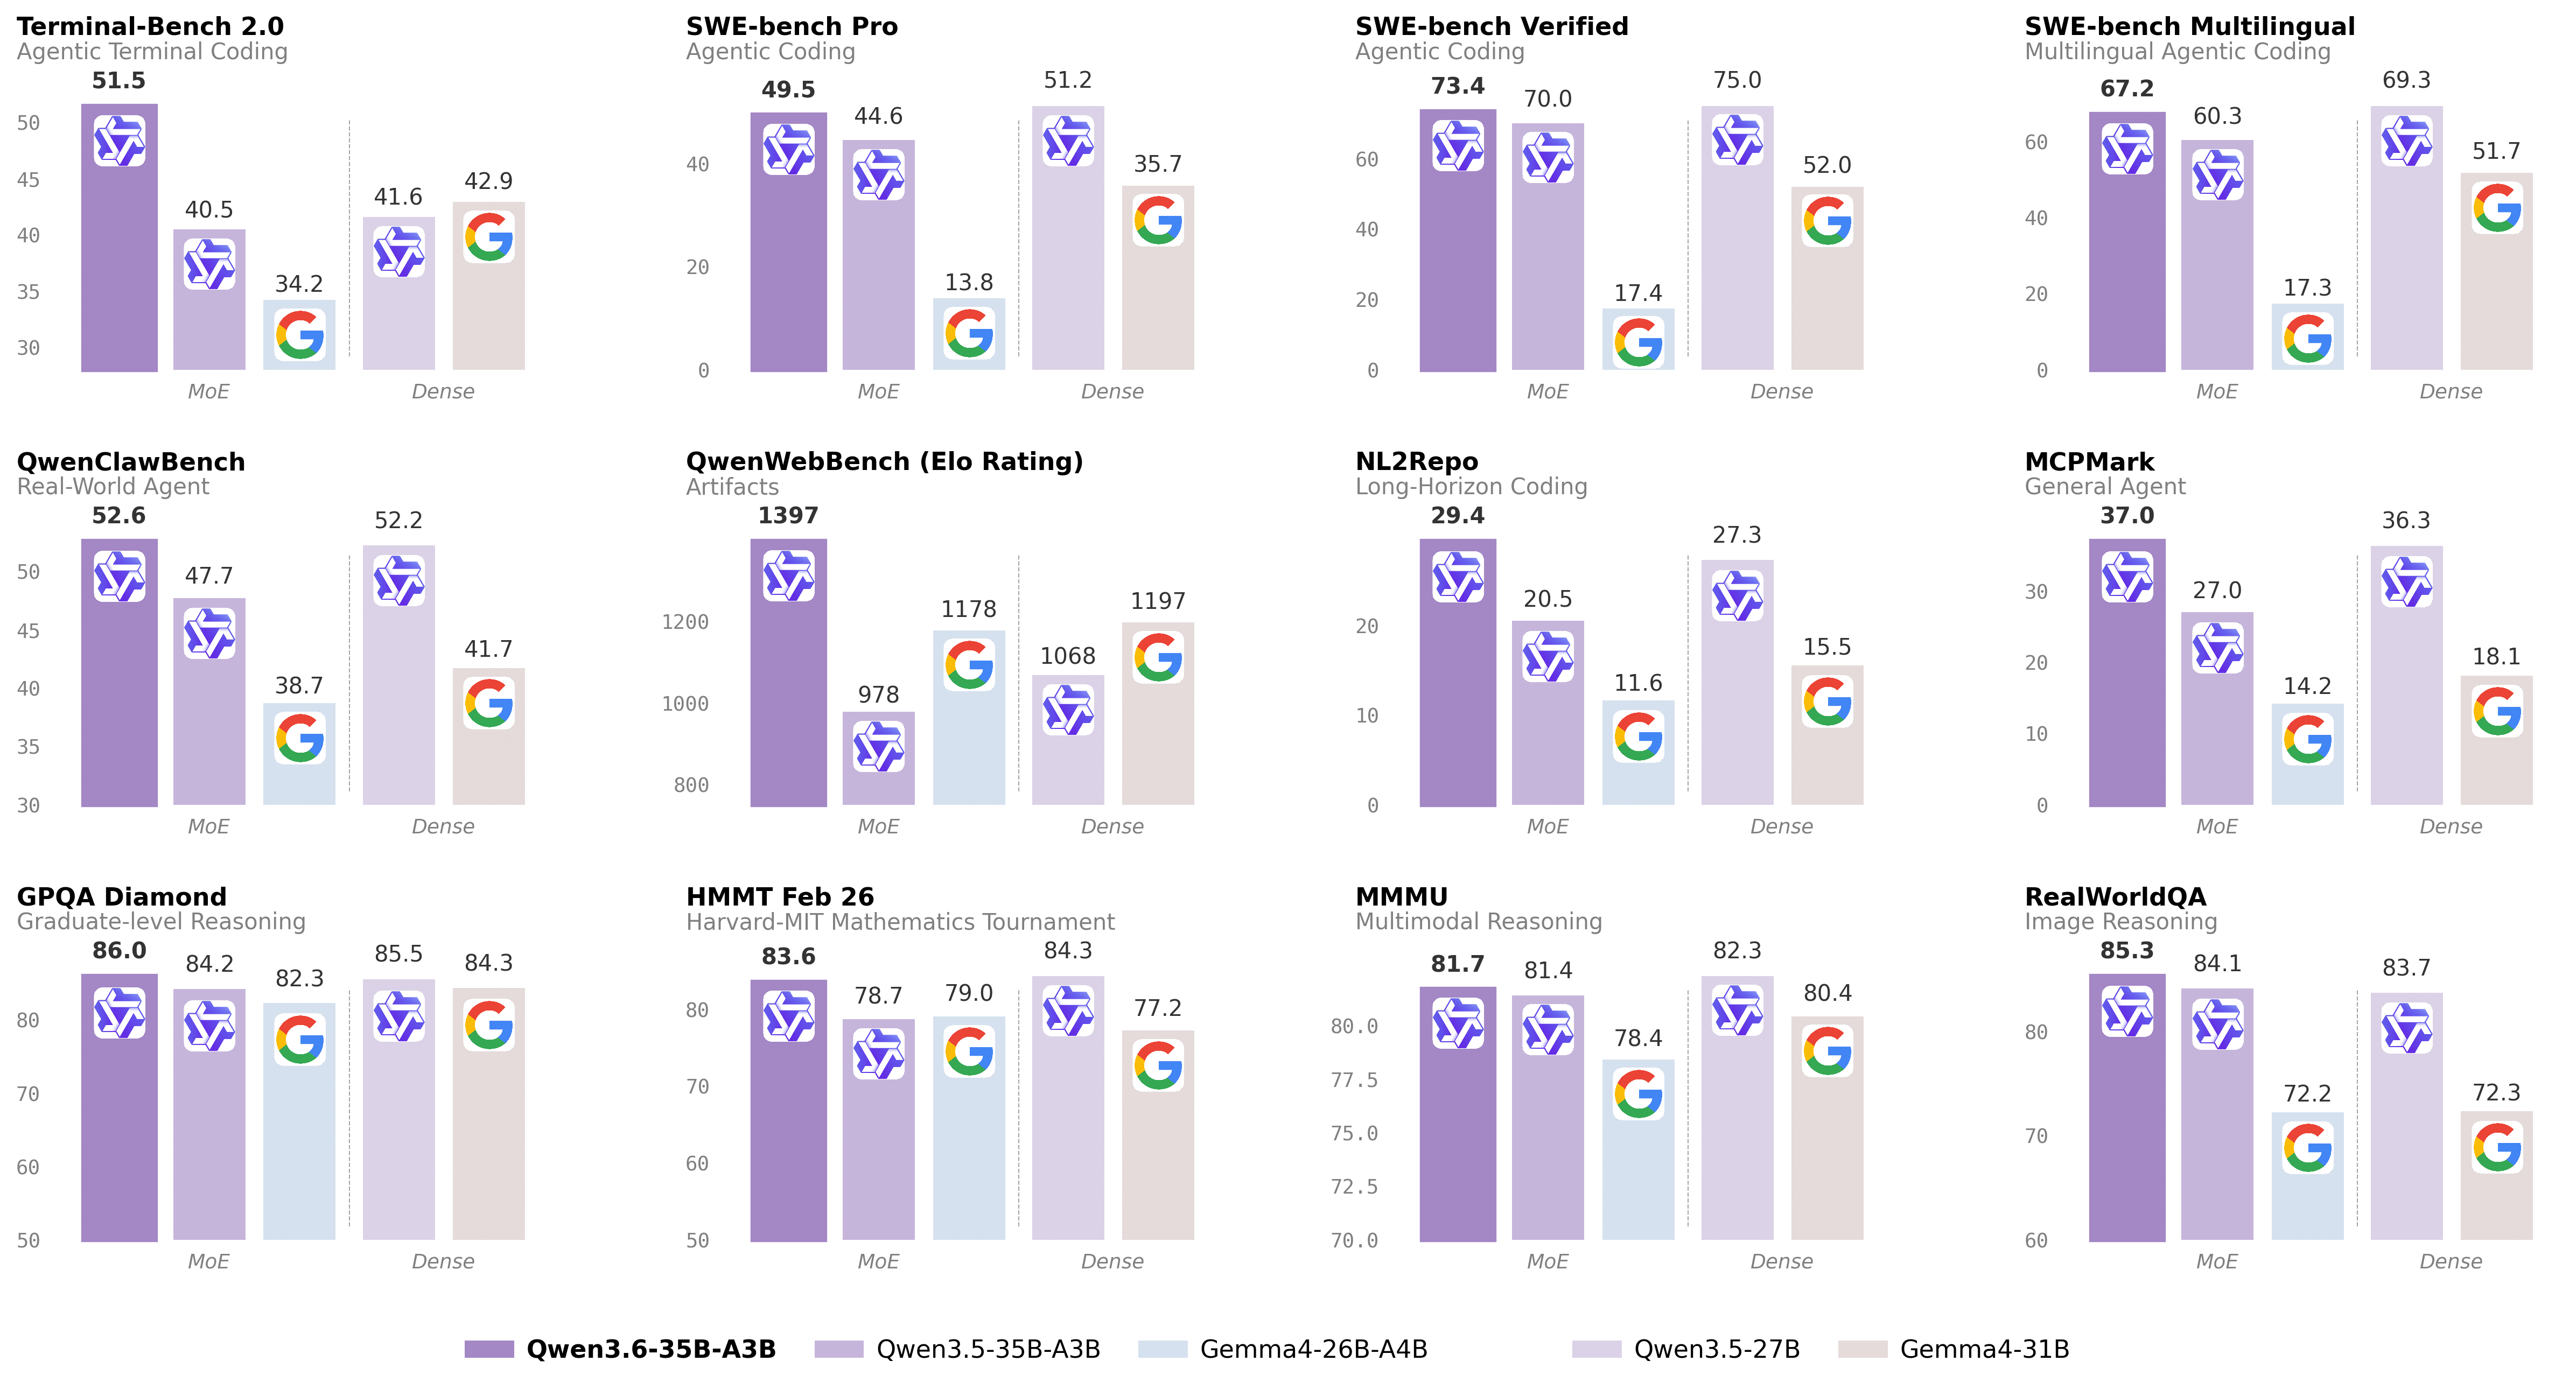
A reasoning SFT fine-tune of `Qwen/Qwen3.6-35B-A3B` on chain-of-thought (CoT) distillation mostly sourced from Claude Opus 4.6. The goal is to preserve Qwen3.6's strong agentic coding and reasoning base while nudging the model toward structured Claude Opus-style reasoning traces and more stable long-form problem solving.
The training path is text-only. The Qwen3.6 base architecture includes a vision encoder, but this fine-tuning run did not train on image or video examples.
- **Developed by:** @hesamation
- **Base model:** `Qwen/Qwen3.6-35B-A3B`
- **License:** apache-2.0
This fine-tuning run is inspired by Jackrong/Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled, including the notebook/training workflow style and Claude Opus reasoning-distillation direction.
[](https://x.com/Hesamation) [](https://discord.gg/vtJykN3t)
## Benchmark Results
The MMLU-Pro pass used 70 total questions per model: `--limit 5` across 14 MMLU-Pro subjects. Treat this as a smoke/comparative check, not a release-quality full benchmark.
...
Repository: localaiLicense: apache-2.0
nanbeige4.1-3b-q8
Nanbeige4.1-3B is built upon Nanbeige4-3B-Base and represents an enhanced iteration of our previous reasoning model, Nanbeige4-3B-Thinking-2511, achieved through further post-training optimization with supervised fine-tuning (SFT) and reinforcement learning (RL). As a highly competitive open-source model at a small parameter scale, Nanbeige4.1-3B illustrates that compact models can simultaneously achieve robust reasoning, preference alignment, and effective agentic behaviors.
Key features:
Strong Reasoning: Capable of solving complex, multi-step problems through sustained and coherent reasoning within a single forward pass, reliably producing correct answers on benchmarks like LiveCodeBench-Pro, IMO-Answer-Bench, and AIME 2026 I.
Robust Preference Alignment: Outperforms same-scale models (e.g., Qwen3-4B-2507, Nanbeige4-3B-2511) and larger models (e.g., Qwen3-30B-A3B, Qwen3-32B) on Arena-Hard-v2 and Multi-Challenge.
Agentic Capability: First general small model to natively support deep-search tasks and sustain complex problem-solving with >500 rounds of tool invocations; excels in benchmarks like xBench-DeepSearch (75), Browse-Comp (39), and others.
Repository: localaiLicense: apache-2.0
nanbeige4.1-3b-q4
Nanbeige4.1-3B is built upon Nanbeige4-3B-Base and represents an enhanced iteration of our previous reasoning model, Nanbeige4-3B-Thinking-2511, achieved through further post-training optimization with supervised fine-tuning (SFT) and reinforcement learning (RL). As a highly competitive open-source model at a small parameter scale, Nanbeige4.1-3B illustrates that compact models can simultaneously achieve robust reasoning, preference alignment, and effective agentic behaviors.
Key features:
Strong Reasoning: Capable of solving complex, multi-step problems through sustained and coherent reasoning within a single forward pass, reliably producing correct answers on benchmarks like LiveCodeBench-Pro, IMO-Answer-Bench, and AIME 2026 I.
Robust Preference Alignment: Outperforms same-scale models (e.g., Qwen3-4B-2507, Nanbeige4-3B-2511) and larger models (e.g., Qwen3-30B-A3B, Qwen3-32B) on Arena-Hard-v2 and Multi-Challenge.
Agentic Capability: First general small model to natively support deep-search tasks and sustain complex problem-solving with >500 rounds of tool invocations; excels in benchmarks like xBench-DeepSearch (75), Browse-Comp (39), and others.
Repository: localaiLicense: apache-2.0

silero-vad-sherpa
Silero VAD served through the sherpa-onnx backend. Uses the same ONNX weights as the dedicated silero-vad backend, loaded through sherpa-onnx's C VAD API. Pairs with the sherpa-onnx ASR entries for round-trip audio pipelines.
Repository: localaiLicense: mit
deepseek-v4-flash-spark-exl3-vllm-cpp
DeepSeek V4 Flash's Spark and GB10-oriented REAP-K216 EXL3 checkpoint,
served by vllm.cpp. It needs CUDA and roughly 100 GiB for its large
rank-sliced checkpoint.
The repository is pinned to its latest recorded revision. vllm.cpp's
existing runtime evidence measured the older 22f28d32b9b29b4352eaa380ff8c2c170b2847ab
revision; this entry does not claim that the newer revision has passed the
same end-to-end gate.
Repository: localai
Page 1