Filter by type:
Filter by tags:

deepseek-v4.1-flash-1017
# DeepSeek-V4.1-Flash-1017
Technical Report 👁️
## Introduction
**DeepSeek-V4.1-Flash-1017** is a minor update to **DeepSeek-V4.1-Flash**, delivering substantial improvements across reasoning, coding, agentic tasks, and visual benchmarks. Alongside these gains, the model reduces task execution time and output length, enabling users to complete tasks faster and at lower cost and advancing the performance–cost Pareto frontier across multiple agent harnesses.
*† denotes the text-only subset of HLE. We use the Claude Code harness for Terminal-Bench 4.0 and the Mini-SWE-V2 harness for DeepSWE v1.1.*
## Prompt Encoding
This release does not include a Jinja-format chat template. The `encoding` folder contains a self-contained Python reference implementation (`encoding.py`) with test cases for multi-turn conversations, tool calling, thinking mode, numeric reasoning effort, mid-conversation system messages, and interleaved image content.
...
Repository: localaiLicense: mit

huihui-qwen3.8-flash-next-abliterated-v2-q4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the
abliteration without modifying the experts. This vision-language
mixture-of-experts model uses the publisher's UD-Q4_K_XL GGUF
and BF16 projector for text chat and image input through llama.cpp.
The default context is 32,768 tokens. Model weights use the
Qwen Community License 1.0.
Repository: localaiLicense: other
huihui-qwen3.8-flash-next-abliterated-v2-iq4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the
abliteration without modifying the experts. This vision-language
mixture-of-experts model uses the publisher's UD-IQ4_XS GGUF
and BF16 projector for text chat and image input through llama.cpp.
The default context is 32,768 tokens. Model weights use the
Qwen Community License 1.0.
Repository: localaiLicense: other

glm-5.3-flash-maya-s
GLM-5.3-Flash is a mixture-of-experts model for reasoning, coding, tool use, and vision. Maya-S v2 mixes IQ2_XXS and IQ2_S experts with Q6_K attention and shared experts.
Repository: localaiLicense: mit
glm-5.3-flash-maya-s24
GLM-5.3-Flash is a mixture-of-experts model for reasoning, coding, tool use, and vision. Maya-S24 uses mixed 2-bit experts with Q4_K attention and shared experts.
Repository: localaiLicense: mit
glm-5.3-flash-maya-m
GLM-5.3-Flash is a mixture-of-experts model for reasoning, coding, tool use, and vision. Maya-M uses mixed 2-bit and 3-bit experts with Q6_K attention and shared experts.
Repository: localaiLicense: mit
glm-5.3-flash-maya-l
GLM-5.3-Flash is a mixture-of-experts model for reasoning, coding, tool use, and vision. Maya-L uses mixed 3-bit and 4-bit experts with higher precision in sensitive layers.
Repository: localaiLicense: mit
qwen3.8-flash-next-uncensored
# Qwen3.8-Flash-Next
> [!Note]
> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
>
> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.
> [!Tip]
> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud.
>
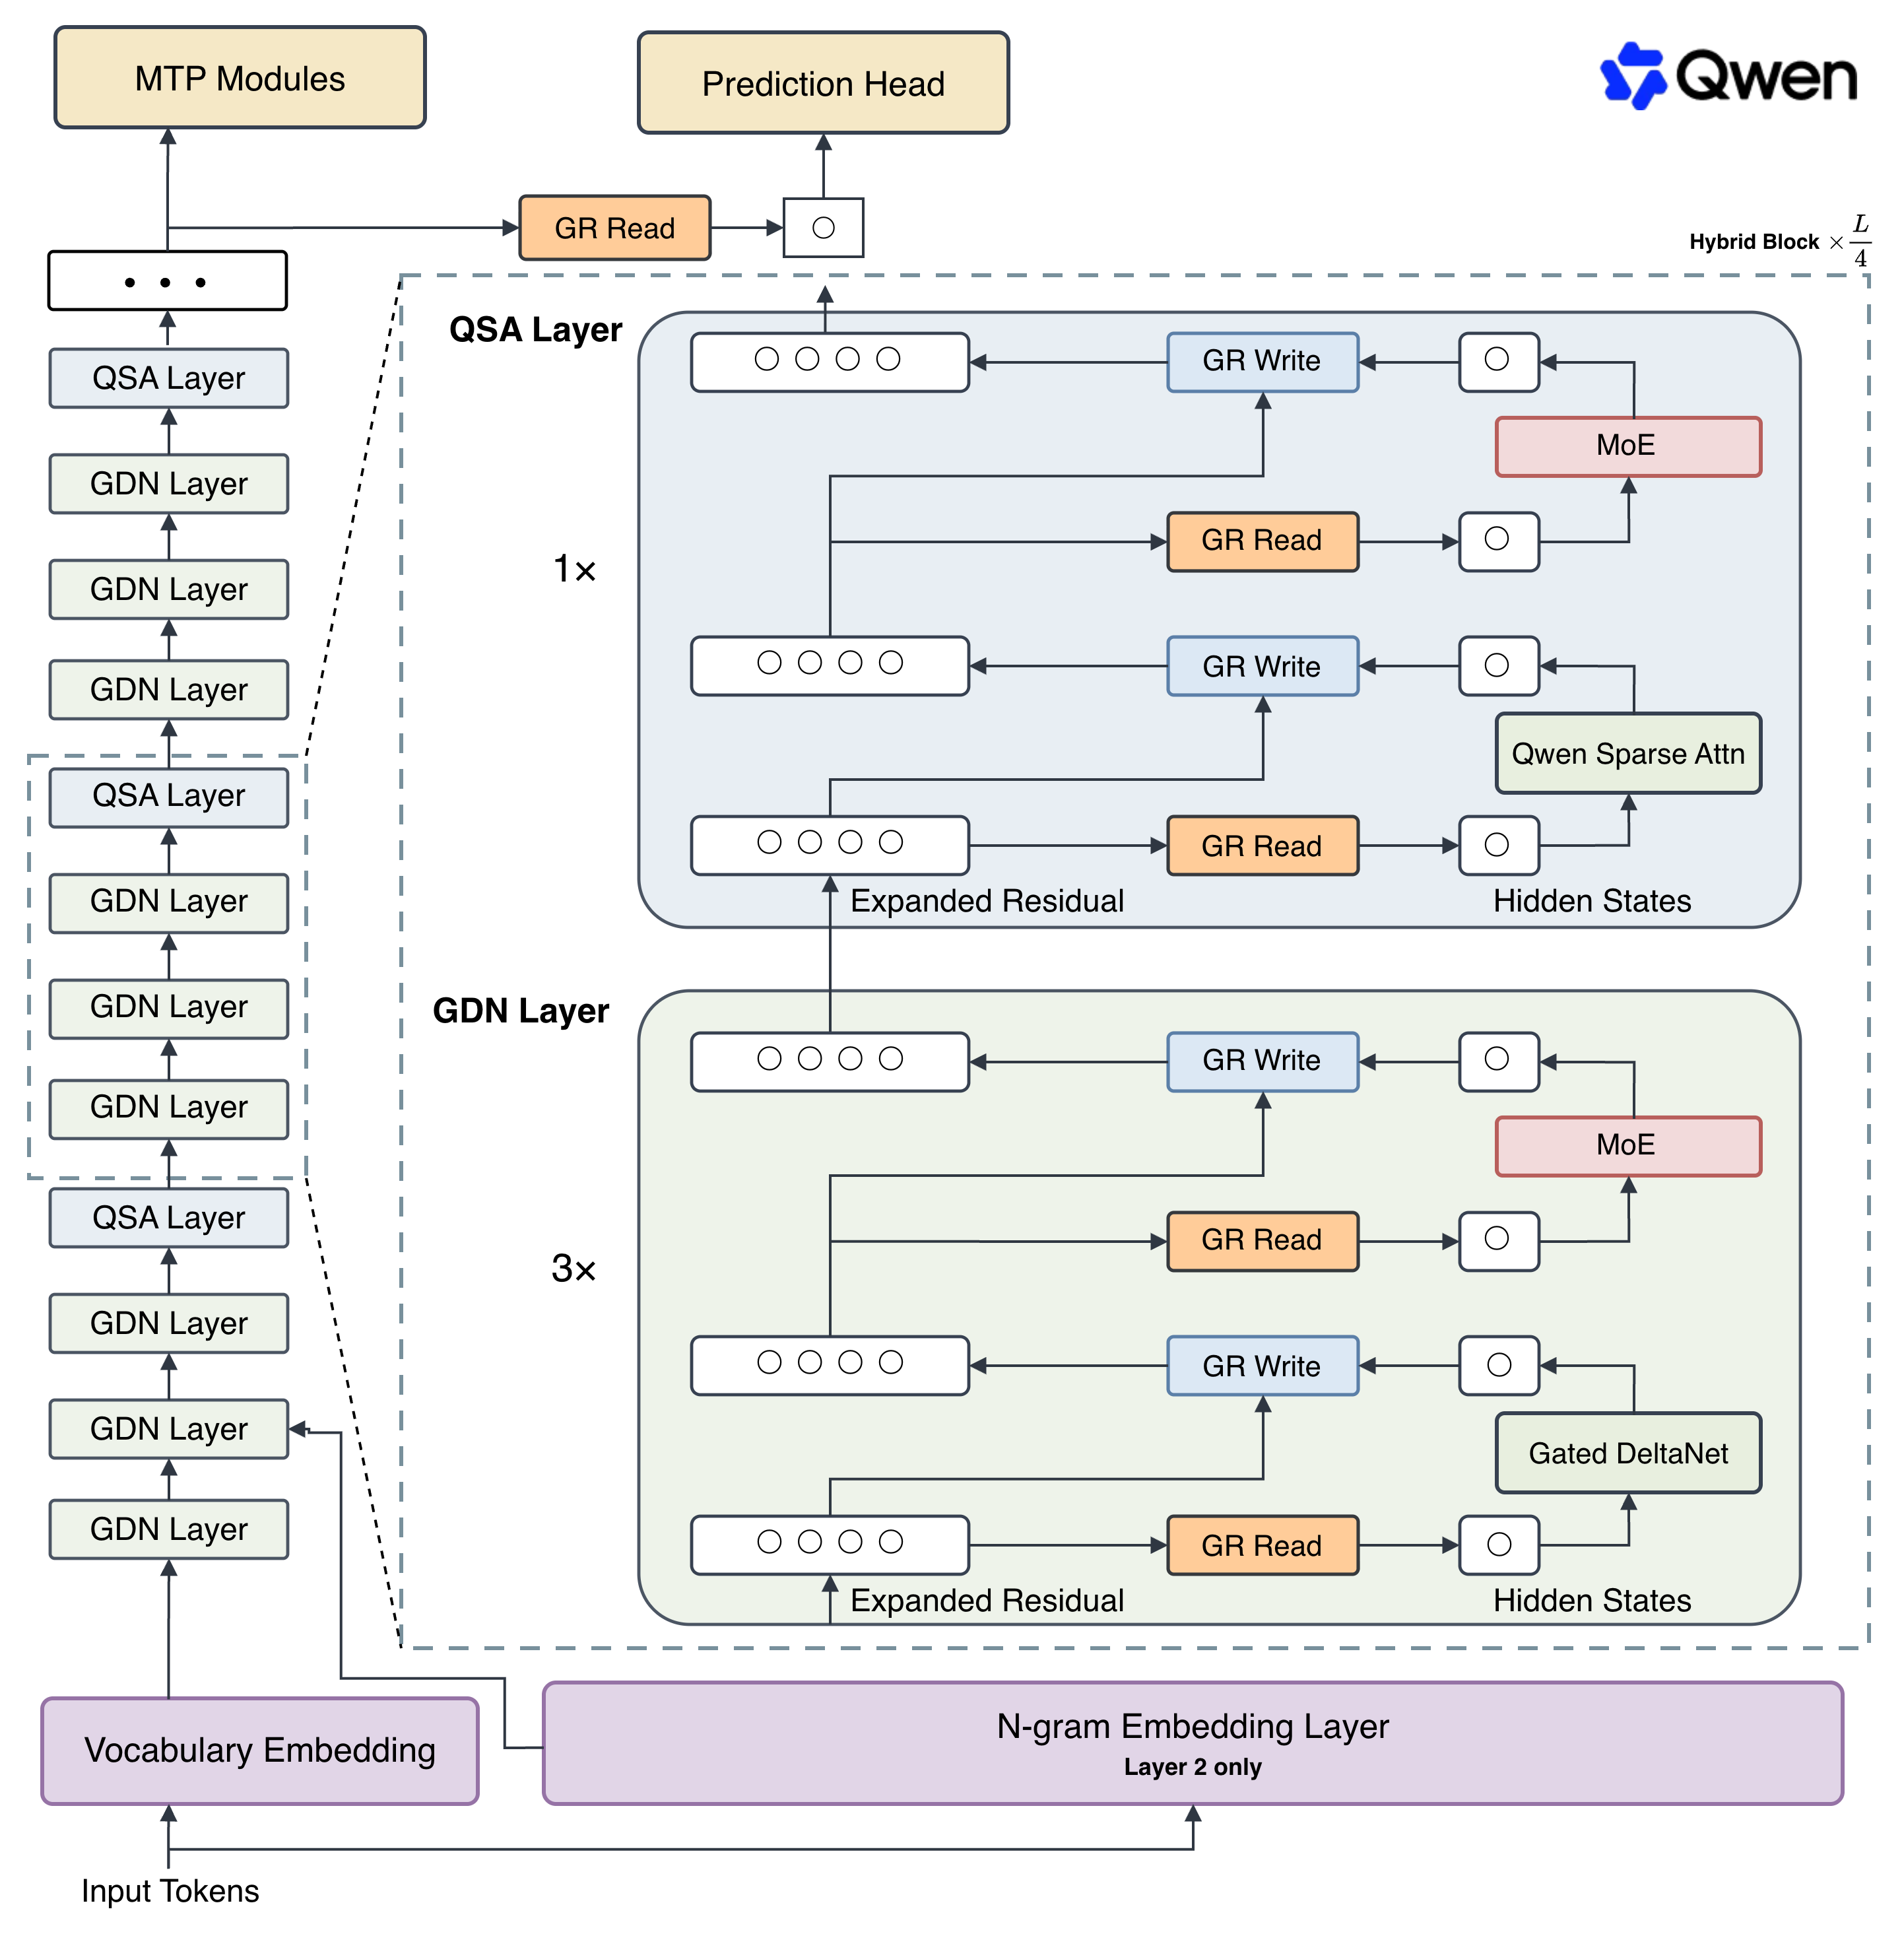
> In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview.
As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next.
...
Repository: localaiLicense: apache-2.0
deepseek-v4-flash-vision-exp
# DeepSeek-V4-Flash-Vision-Exp
## Introduction
We are excited to introduce **DeepSeek-V4-Flash-Vision-Exp**, our first experimental multimodal model in the DeepSeek-V4 family. It builds on the DeepSeek-V4-Flash architecture by incorporating visual modules and undergoing continued training to unlock visual understanding capabilities.
Compared to DeepSeek-V4-Flash-0731, DeepSeek-V4-Flash-Vision-Exp achieves substantial improvements on its multimodal agent capabilities, while maintaining comparable performance on text-only agent tasks.
Notes:
1. For the text agent benchmarks above, DeepSeek models are evaluated with the minimal mode of DeepSeek Harness as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`.
2. † For ApexBench and Agents' Last Exam, DeepSeek-V4-Flash-0731 ignores the multimodal elements in the input.
## Repository layout
This repository contains the tokenizer, prompt encoding reference, and a
minimal PyTorch inference implementation for DeepSeek-V4 Flash Vision. The
reference inference covers the vision encoder and aligner, DFlash attention,
MoE, Hyper-Connections, and the DSpark forward path.
...
Repository: localaiLicense: mit
qwopus3.8-27b-flash-v2
Qwopus3.8-27B-Flash-V2 is a new post-training release for reasoning and agent
workloads. This Q4_K_M GGUF includes the F32 vision projector and uses
llama.cpp's embedded chat template with MTP speculative decoding.
Repository: localaiLicense: apache-2.0
qwopus3.8-27b-flash-v2-q8
Qwopus3.8-27B-Flash-V2 is a new post-training release for reasoning and agent
workloads. This Q8_0 GGUF includes the F32 vision projector and uses
llama.cpp's embedded chat template with MTP speculative decoding.
Repository: localaiLicense: apache-2.0
qwopus3.8-27b-flash
Qwopus3.8-27B-Flash is a Qwen3.8-27B fine-tune for reasoning and agent
workloads. This Q4_K_M GGUF includes the F32 vision projector and uses
llama.cpp's embedded chat template with MTP speculative decoding.
The publisher reports a known Python code indentation issue.
Repository: localaiLicense: apache-2.0
qwopus3.8-27b-flash-q8
Qwopus3.8-27B-Flash is a Qwen3.8-27B fine-tune for reasoning and agent
workloads. This Q8_0 GGUF includes the F32 vision projector and uses
llama.cpp's embedded chat template with MTP speculative decoding.
The publisher reports a known Python code indentation issue.
Repository: localaiLicense: apache-2.0
glm-5.3-flash
# GLM-5.3-Flash
👋 Join our WeChat or Discord community.
📖 Check out the GLM-5.3-Flash blog and GLM-5 Technical report.
📍 Use GLM-5.3-Flash API services on Z.ai API Platform.
## Introduction
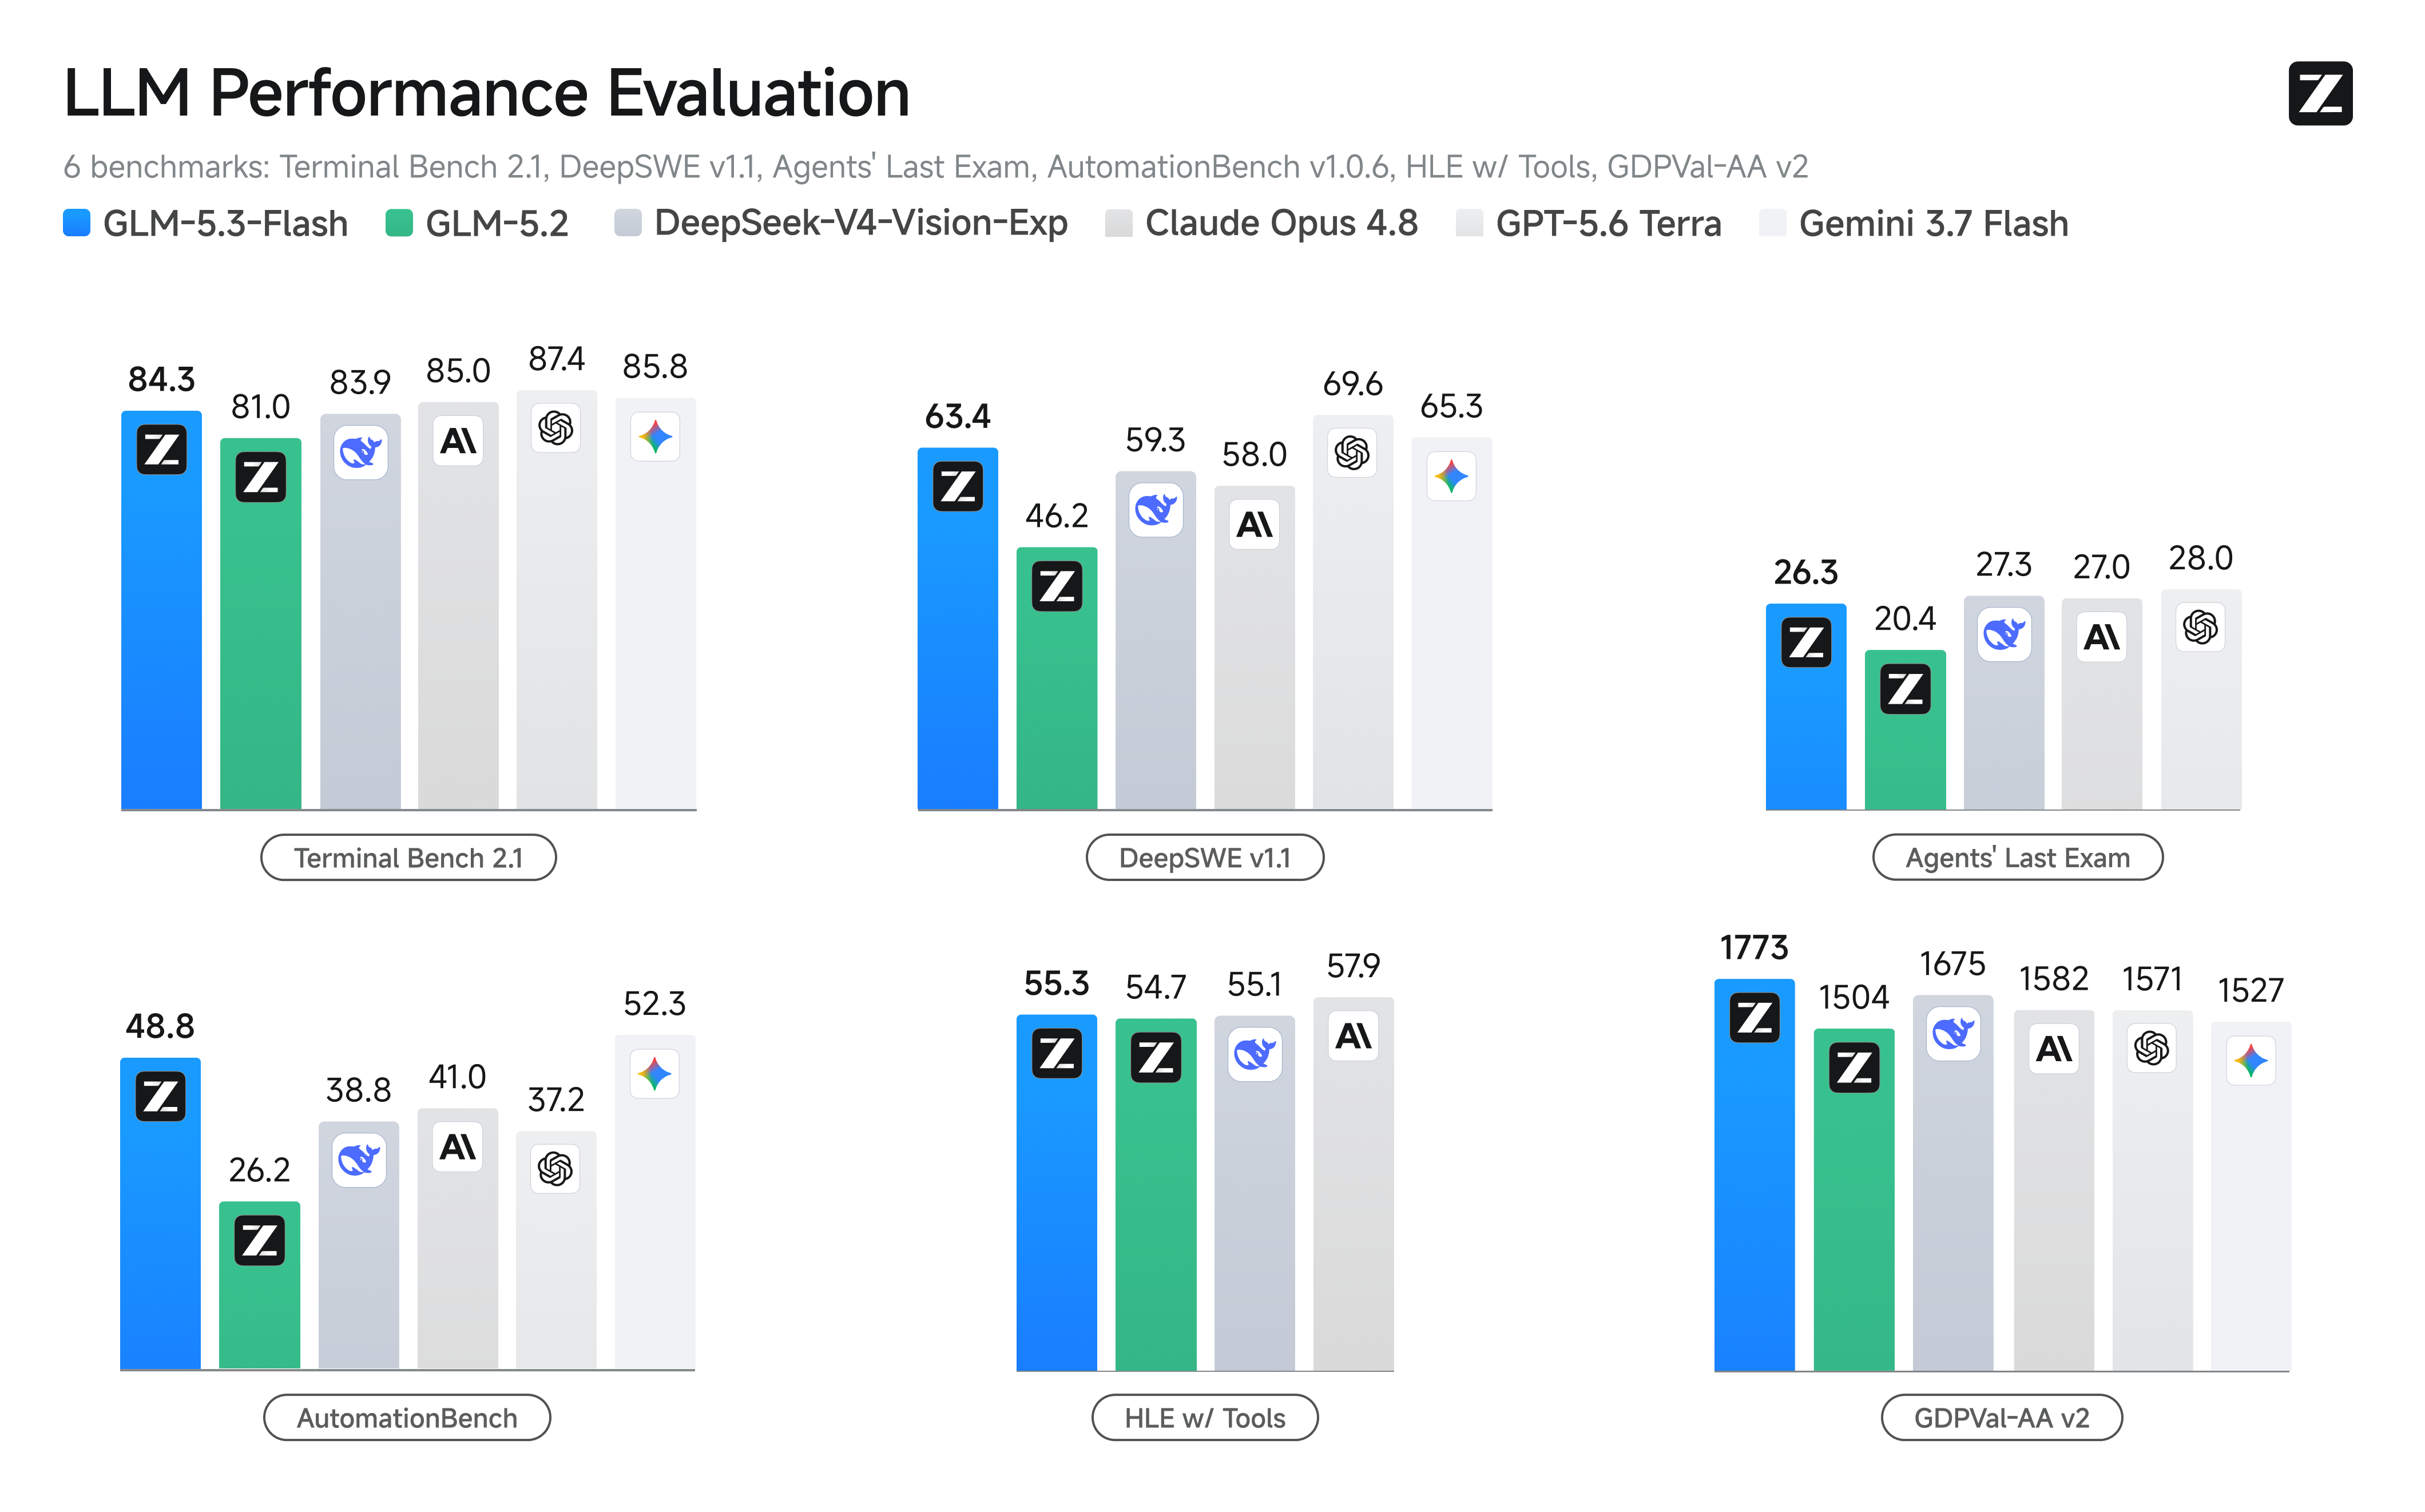
We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it outperforms GLM-5.2 across benchmarks and real-world workloads at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks.
GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. For the first time in the GLM series, we introduce a hybrid architecture combining sparse and linear attention, sharply reducing long-context serving costs while preserving precise long-context capabilities. The model also adopts Manifold-Constrained Hyper-Connections (mHC) to further improve scaling efficiency. Together with our latest 30T-token multimodal pre-training corpus, these changes enable GLM-5.3-Flash to deliver more intelligence with less compute.
## Serve GLM-5.3-Flash Locally
...
Repository: localaiLicense: mit
glm-5.3-flash-q4
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts
model with 18B active parameters. It combines sparse and linear attention
for coding, agentic work, tool use, vision, and long-context tasks. This
entry uses the UD-Q4_K_XL GGUF quantization and enables the model's MTP
speculative-decoding head.
Repository: localaiLicense: mit
glm-5.3-flash-q8
GLM-5.3-Flash is Z.ai's natively multimodal 320B-parameter mixture-of-experts
model with 18B active parameters. It combines sparse and linear attention
for coding, agentic work, tool use, vision, and long-context tasks. This
entry uses the higher-quality Q8_0 GGUF quantization and enables the model's
MTP speculative-decoding head.
Repository: localaiLicense: mit
huihui-qwen3.8-flash-next-abliterated-q4
Huihui's abliterated Qwen3.8-Flash-Next is a vision-language
mixture-of-experts model modified to reduce refusals. This entry uses
the publisher's UD-Q4_K_XL GGUF and BF16 vision projector for text chat
and image input through llama.cpp. The default context is 32,768 tokens.
Model weights use the Qwen Community License 1.0.
Repository: localaiLicense: other
qwen3.8-flash-next-q4
Qwen3.8-Flash-Next is Qwen's 125B-parameter, 6B-active experimental
vision-language mixture-of-experts model. It targets agentic coding,
reasoning, tool use, and long-context workloads with a native 262K-token
context window.
This default entry uses Unsloth's UD-Q4_K_XL GGUF and BF16 vision
projector. Linked variants offer Q8_0 and AtomicChat's smaller IQ4_XS
and Q4_K_M builds with a separate n-gram table shard.
Repository: localaiLicense: other
qwen3.8-flash-next-q8
Qwen3.8-Flash-Next in the higher-quality Q8_0 GGUF format, with the shared
BF16 vision projector. This build preserves more model quality but needs
more memory than the default Q4 variant.
Repository: localaiLicense: other
qwen3.8-flash-next-turbo-brilliance-iq3-s
DavidAU's Turbo Brilliance build of Qwen3.8 Flash Next uses GSQ-RCO
IQ3_S mixed quantization and the publisher's embedded chat template.
Includes both GGUF shards and the BF16 vision projector for text chat
and image input, with a 32K default context. See the model card for
the publisher's reasoning and instruction modes.
Repository: localaiLicense: other
qwen3.8-flash-next-gsq-rco-q2-0
Qwen3.8 Flash Next with ISTA DASLab's GSQ-RCO Q2_0 mixed quantization.
Includes both GGUF shards (transformer weights and n-gram embeddings)
and the BF16 vision projector for text chat and image input.
Uses llama.cpp with the embedded chat template and a 32K context.
Repository: localaiLicense: other
Page 1