Model Gallery

206 models from 1 repositories

Filter by type:

Filter by tags:

spark-x2.6-4b-q4
Spark-X2.6-4B is XHToken's 4B text model for conversation, reasoning, coding, and multilingual tasks. This build uses Q4_K_M GGUF weights, the embedded Jinja chat template, and a 32K-token default context.

Repository: localaiLicense: apache-2.0

spark-x2.6-4b-q8
Spark-X2.6-4B is XHToken's 4B text model for conversation, reasoning, coding, and multilingual tasks. This build uses Q8_0 GGUF weights, the embedded Jinja chat template, and a 32K-token default context.

Repository: localaiLicense: apache-2.0
ornith-1.5-122b-ud-q4-k-xl
Ornith 1.5 122B is a Qwen3.5 mixture-of-experts model for reasoning, coding, and tool use. This UD-Q4_K_XL GGUF build includes the F16 vision projector for image input and uses an 8,192-token default context.

Repository: localaiLicense: mit

ornith-1.5-122b-q8
Ornith 1.5 122B is a Qwen3.5 mixture-of-experts model for reasoning, coding, and tool use. This Q8_0 GGUF build includes the F16 vision projector for image input and uses an 8,192-token default context.

Repository: localaiLicense: mit

diplodocus-preview-q4
Diplodocus preview 4 is OsaurusAI's K2 Horizon 7B fine-tune for documents, spreadsheets, and tool-assisted tasks. This Q4_K_M GGUF build uses the embedded chat template and enables reasoning by default. Applications must provide the tools; the model download does not include workspace tools.

Repository: localaiLicense: apache-2.0

diplodocus-preview-q6
Diplodocus preview 4 is OsaurusAI's K2 Horizon 7B fine-tune for documents, spreadsheets, and tool-assisted tasks. This Q6_K GGUF build uses the embedded chat template and enables reasoning by default. Applications must provide the tools; the model download does not include workspace tools.

Repository: localaiLicense: apache-2.0

diplodocus-preview-q8
Diplodocus preview 4 is OsaurusAI's K2 Horizon 7B fine-tune for documents, spreadsheets, and tool-assisted tasks. This Q8_0 GGUF build uses the embedded chat template and enables reasoning by default. Applications must provide the tools; the model download does not include workspace tools.

Repository: localaiLicense: apache-2.0

atomic-minicpm-v-4.7-35b-a3b-uncensored-q4
AtomicChat's abliterated MiniCPM-V 4.7 is a 35B mixture-of-experts model with 3B active parameters for chat and image understanding. This AD-Q4_K-IQ4_XS build includes all 11 weight shards and the F16 vision projector, with the embedded chat template and a 32K-token default context.

Repository: localaiLicense: apache-2.0

atomic-minicpm-v-4.7-35b-a3b-uncensored-q6
AtomicChat's abliterated MiniCPM-V 4.7 is a 35B mixture-of-experts model with 3B active parameters for chat and image understanding. This AD-Q6_K build includes all 16 weight shards and the F16 vision projector, with the embedded chat template and a 32K-token default context.

Repository: localaiLicense: apache-2.0

huihui-qwen3.8-flash-next-abliterated-v2-q4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the abliteration without modifying the experts. This vision-language mixture-of-experts model uses the publisher's UD-Q4_K_XL GGUF and BF16 projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

huihui-qwen3.8-flash-next-abliterated-v2-iq4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the abliteration without modifying the experts. This vision-language mixture-of-experts model uses the publisher's UD-IQ4_XS GGUF and BF16 projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

qwen3.8-flash-next-uncensored
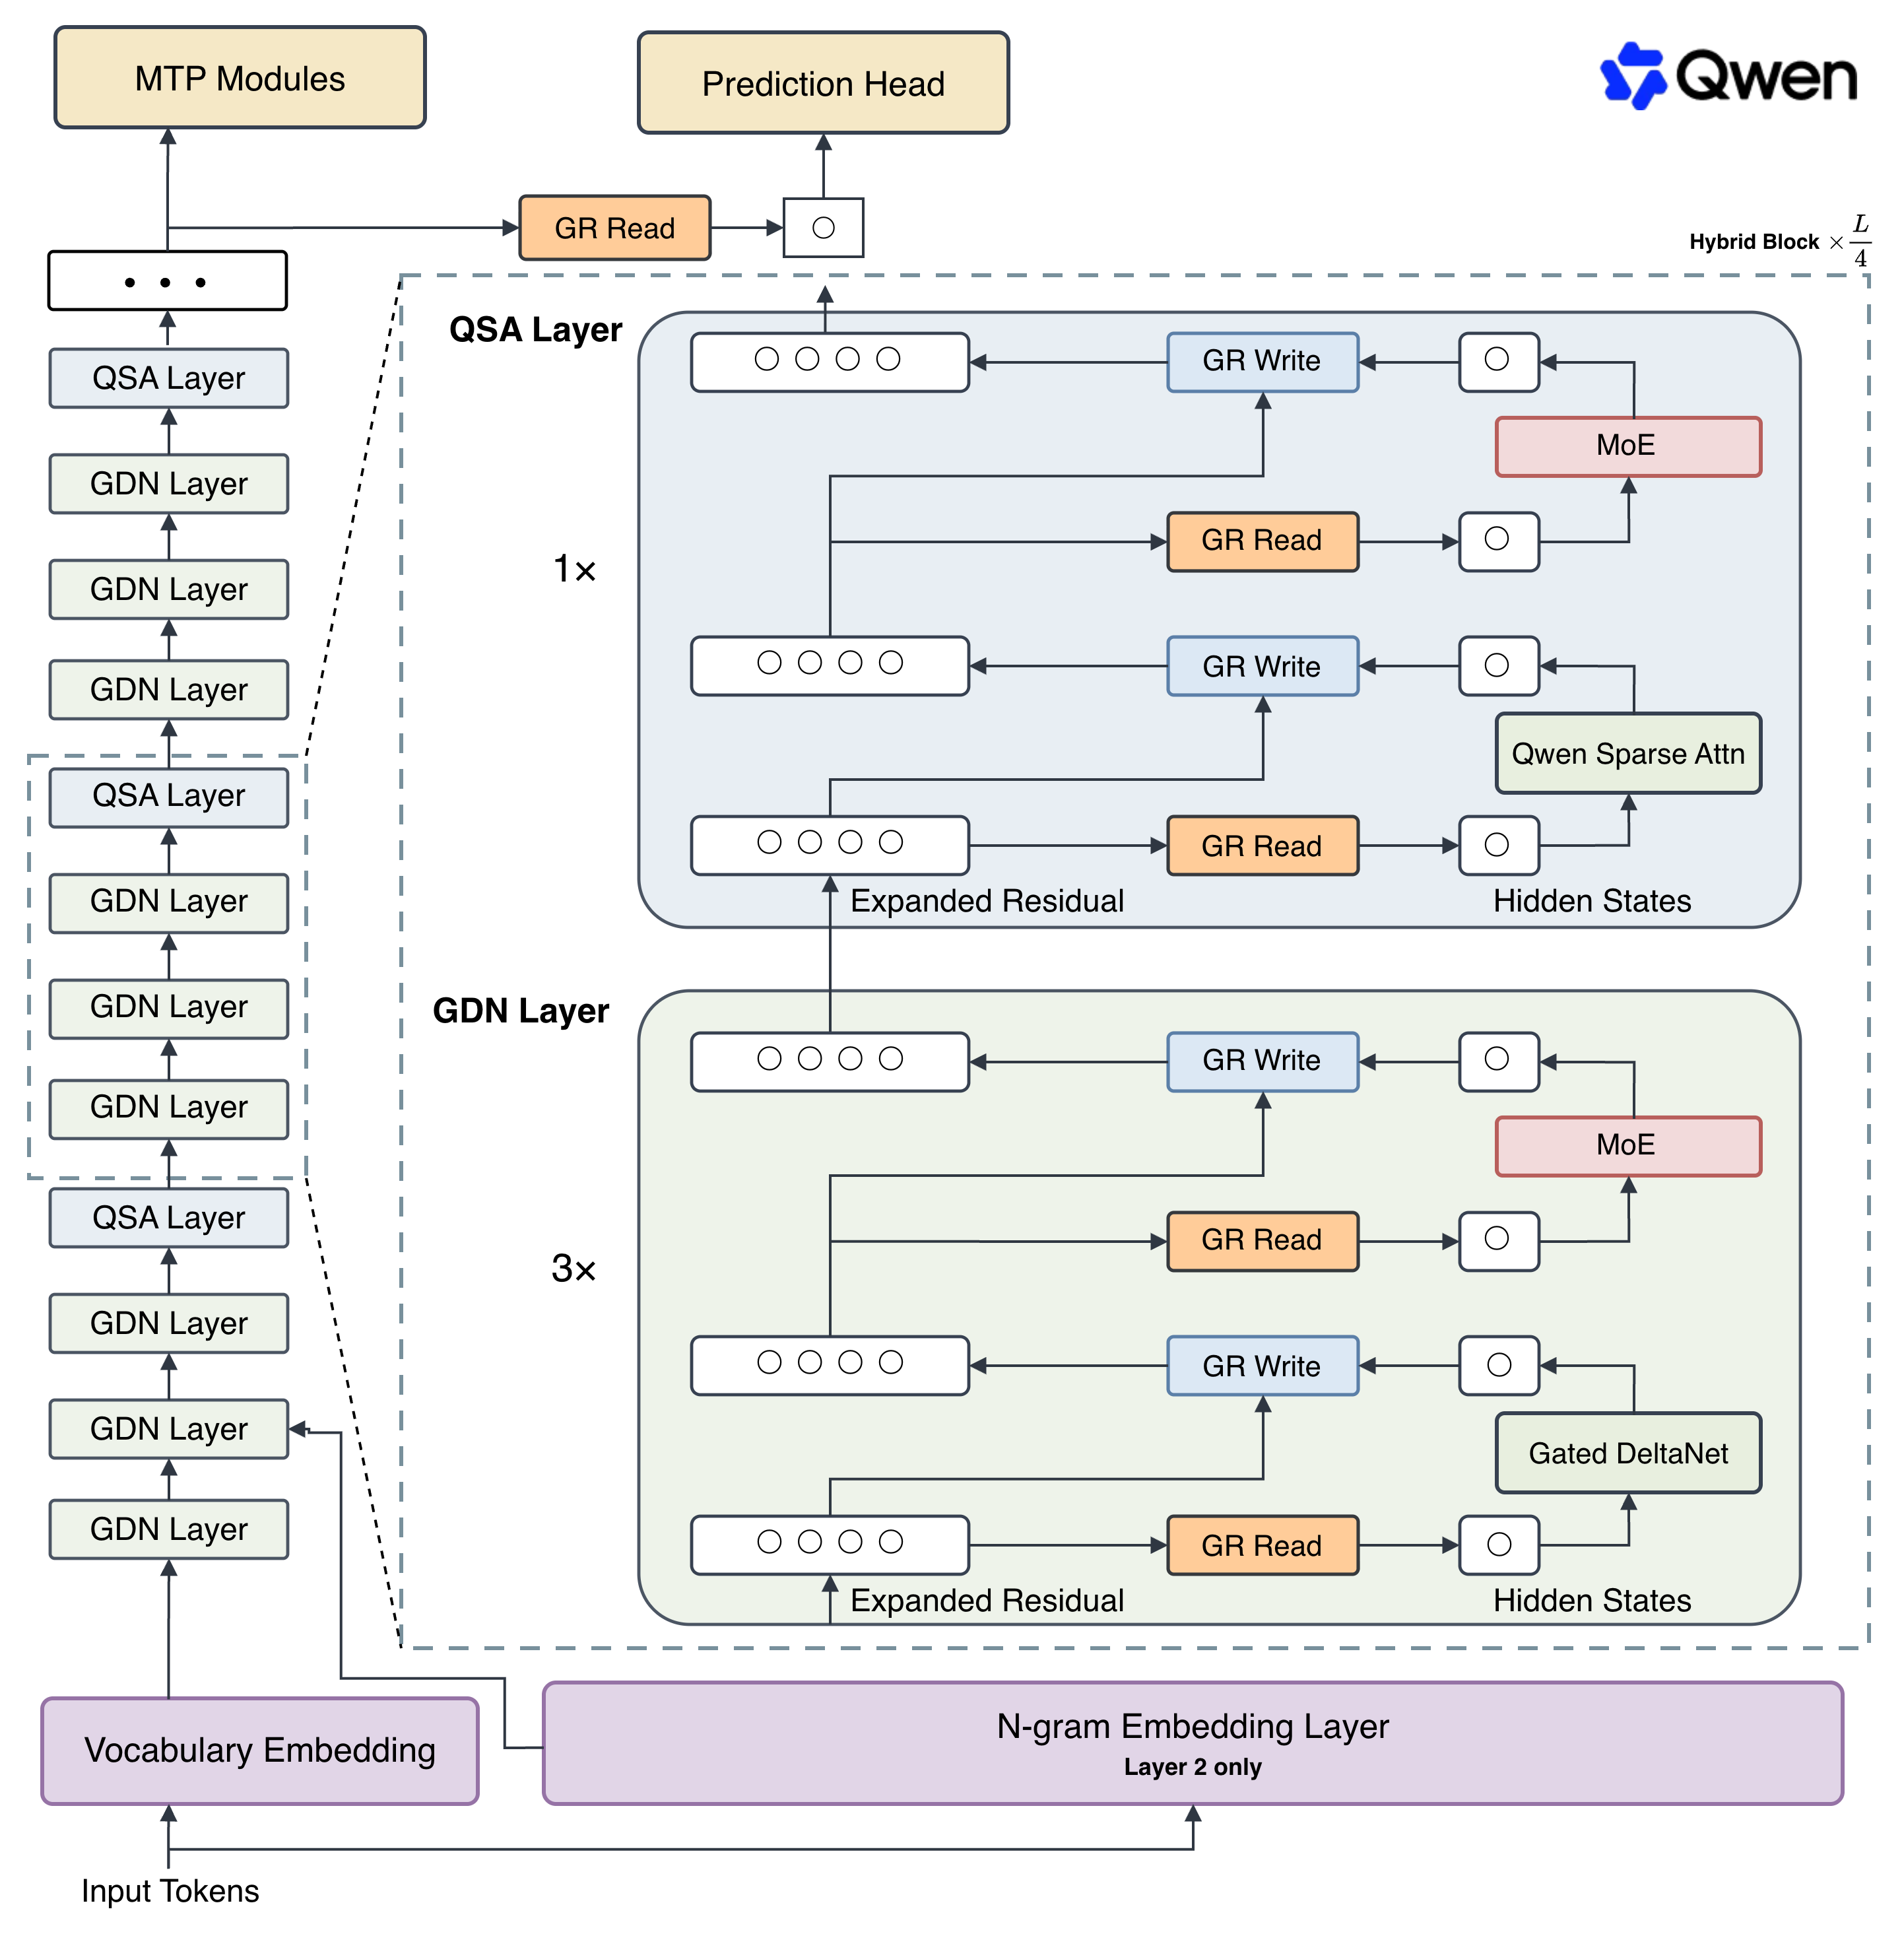
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-jumbo-fusion-q4
DavidAU's Jumbo Fusion edition of Qwen3.8-27B merges community fine-tunes and includes a custom template with reasoning and instruction modes. This Q4_K_M GGUF build supports text chat with a 32,768-token default context.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-jumbo-fusion-q8
DavidAU's Jumbo Fusion edition of Qwen3.8-27B merges community fine-tunes and includes a custom template with reasoning and instruction modes. This Q8_0 GGUF build supports text chat with a 32,768-token default context.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-turbo-brilliance-50x-q4
DavidAU's Turbo Brilliance 50X edition of Qwen3.8-27B includes a custom chat template with selectable reasoning and instruction modes. This Q4_K_M GGUF build includes the F16 vision projector for image input. Uses the embedded template with a 32,768-token context by default.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-turbo-brilliance-50x-q8
DavidAU's Turbo Brilliance 50X edition of Qwen3.8-27B includes a custom chat template with selectable reasoning and instruction modes. This Q8_0 GGUF build includes the F16 vision projector for image input. Uses the embedded template with a 32,768-token context by default.

Repository: localaiLicense: apache-2.0

qwen3.8-27b
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-uncensored-hauhaucs-aggressive-mtp
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-uncensored
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

apodex-1.1-mini-q4
Apodex-1.1-mini is an Apache-2.0 Qwen3.5 mixture-of-experts model for long-horizon research, data analysis, coding, file work, and tool use. It activates about 3B of its 35.95B parameters per token and supports text and image input with a context window of 262K tokens. This default entry uses the recommended Q4_K_M GGUF and F16 vision projector. An MTP-enabled build and a higher-quality Q8_0 model are available as variants.

Repository: localaiLicense: apache-2.0

s1-mini-q4
S1-mini by Superwhisper is a 0.6B English text normalizer for raw speech transcripts. It removes fillers and false starts, restores punctuation and capitalization, and formats spoken numbers, dates, currency, and email addresses as written text. This default entry uses the publisher's 462 MB Q4_K_M GGUF and greedy decoding. A higher-fidelity F16 model is available as a variant. Prefix the transcript with the styling, structure, and context control line documented on the model page.

Repository: localaiLicense: s1-mini-license

Page 1